LiteLLM is Just the Latest Warning: The Access Model Built on Secrets Is Failing

Micha Rave's avatar
Micha Rave CEO and Co-Founder

Table of Contents

The latest LiteLLM breach should concern security leaders for reasons that go well beyond one compromised open-source project. It’s another entry in a growing list of attacks following an increasingly familiar pattern: attackers gain an initial foothold, obtain credentials, and use those secrets to expand their reach.

We’ve seen this before. We’re seeing it more frequently. And the time between initial compromise and potential damage is shrinking.

In March, LiteLLM was compromised as part of a broader software supply chain campaign that also affected projects including Trivy, Checkmarx, and Telnyx. Seven months later, on October 21, attackers compromised LiteLLM’s release pipeline again, distributing malicious software through its official channels.

Different attacks, same recurring weakness: credentials that can be stolen and reused to turn one compromised system into access to many others.

The real damage begins after the first breach

The October LiteLLM incident shows the problem clearly.

According to LiteLLM’s preliminary investigation, attackers appear to have accessed an exposed internal deployment and obtained GitHub authentication tokens from its logs. Those credentials allowed them to manipulate the release pipeline and distribute a poisoned version of the software.

The malicious release was designed to harvest additional credentials, including cloud access keys, SSH keys, AI provider secrets, and credentials stored in LiteLLM’s own proxy database.

An attacker obtains credentials from one system, uses them to compromise a trusted distribution channel, and turns that channel into a mechanism for collecting credentials from potentially many more systems.

Each successful compromise creates opportunities for the next.

The pace is accelerating

The threat landscape is changing in two ways: attackers have more potential entry points, and the tools available to exploit them are becoming far more capable.

Palo Alto Networks’ 2026 Unit 42 Incident Response Report found that identity weaknesses played a material role in nearly 90% of its investigations. It also reported that the fastest attacks in 2025 exfiltrated data at four times the previous speed.

Meanwhile, advances in AI are making sophisticated offensive capabilities more accessible. Anthropic has demonstrated that its Claude Mythos Preview model can identify and exploit previously unknown vulnerabilities across major operating systems and browsers.

As vulnerability discovery and exploitation become increasingly automated, organizations should expect less time to identify and contain an intrusion.

Preventing breaches still matters. Organizations must continue securing their software supply chains, patching vulnerabilities, and strengthening authentication.

But prevention alone is no longer a sufficient strategy.

Security leaders also need to ask a different question: When an attacker gets in, how much access can they gain, and how quickly can they expand it?

The problem is the access model

For decades, machine-to-machine access has depended heavily on secrets. API keys, service account passwords, tokens, and other credentials are embedded in applications, stored in configuration files, passed through pipelines, and sometimes exposed in logs.

That model was already difficult to secure in traditional infrastructure. Now, organizations are adding thousands of workloads, integrations, and autonomous AI agents that need access to enterprise resources.

Every additional long-lived credential creates another opportunity for theft and reuse. Every overly permissive identity increases the potential blast radius.

Since the news broke, I’ve had calls with security leaders cut short because their teams were busy dealing with the fallout. If your team is one of them, I know how hard it’s been.

Rotating compromised credentials is the right immediate response. But anyone who has done it at scale knows the pain: tracking down every key that might be exposed, pulling engineers off their work, and making sure nothing breaks along the way. And when it’s over, the underlying model is still intact. New secrets replace the old ones, in the same places, with the same exposure.

We need to reduce our dependence on reusable secrets and move toward an access model built around identity, with access continuously governed according to what each workload or agent is authorized to do.

That means:

  • Verified, accountable identities: Every workload and AI agent has a distinct identity, rather than relying on shared, persistent credentials.
  • Just-in-time access: Permissions and credentials are scoped to specific tasks and limited in duration, reducing their value if compromised.
  • Least Agency: AI agents receive only the capabilities their tasks require, with sensitive actions subject to appropriate controls.
  • Continuous runtime visibility: Organizations can see which identities access which resources, detect unusual activity, and enforce policy as access happens.

These controls cannot make a software supply chain compromise impossible. They can, however, make stolen credentials far less useful and substantially limit what an attacker can reach after gaining access.

The next breach is a matter of when

LiteLLM won’t be the last incident of this kind. Another compromised dependency, exposed token, or hijacked release pipeline will make headlines.

The immediate response will again involve investigation, patching, and credential rotation. All of those steps are necessary.

But the more important question is whether organizations will still be exposing the same reusable credentials, granting the same standing privileges, and allowing attackers the same opportunities to move from one system to the next.

As attacks become faster and more frequent, containing their impact becomes just as important as preventing the initial intrusion.

At Hush, this is the future we’re building toward: an identity-based access model for workloads and AI agents, where access is verified, scoped, and governed at runtime without relying on long-lived secrets.

The next breach may be inevitable. The chain of access after it is not.
Find Every AI Agent and NHI, Free
Get a Demo

You Found the Agent. Now Find Out What It Can Do.

Moran Stahi's avatar
Moran Stahi Senior Product Manager

Table of Contents

Hush Entitlements adds access context to every NHI and AI agent

Finding an AI agent is only the beginning.

Agents don’t work alone. They reach your cloud services, data, and infrastructure through credentials and non-human identities (NHIs), and the access granted to those identities determines how far an agent can go. An agent with read access to a development bucket is a very different risk from an agent running as an identity with administrative access to production.

Discovery tells you the agent exists. Entitlements reveal the access behind it.

An Agent Is Only as Powerful as Its Identity

Agents are built to act. They choose tools, call systems, and take steps toward a goal. That means the real security boundary isn’t only what you expect an agent to do. It’s what the identities within its reach allow it to do.

Hush discovers AI agents and MCP servers through runtime activity, including those missing from official inventories, and connects them to the credentials and identities they rely on. With Entitlements, you can now see the access behind each of those identities.

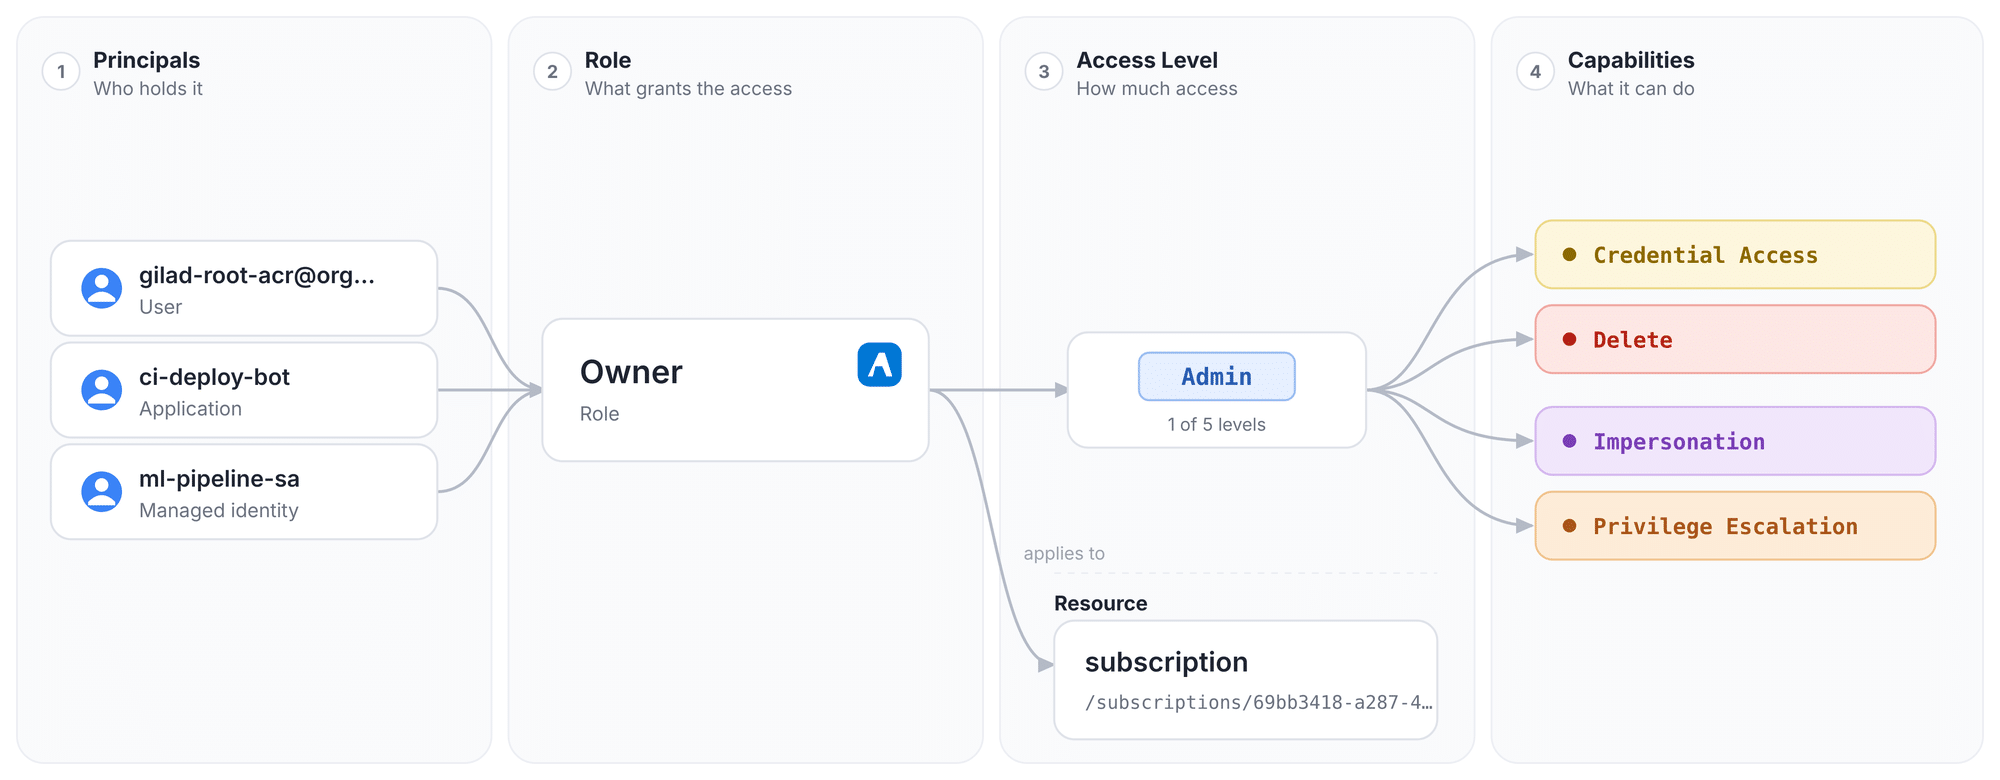
Knowing that an agent uses a service account tells you very little on its own. What matters is the access that service account carries: whether it can read a single resource, or administer production, delete data, and impersonate other identities. Entitlements provide that context, helping you understand how far an agent’s reach could extend.

From a List of Identities to a Picture of Power

Cloud environments run on a growing number of machine identities: service accounts, workload identities, IAM roles, managed identities, and more. Hush already discovers them and ties them to the credentials and workloads that use them. Entitlements add the missing piece: what each identity is actually allowed to do.

Hush Entitlements provides visibility into cloud roles, policies, and permissions across AWS, GCP, and Azure. It connects that access to the identities that hold it, showing what each identity can do, which sensitive capabilities it has, and where its permissions apply – from individual resources to entire cloud accounts and organizations.

This gives security teams a clear view of privileged access across their environment, without having to piece together IAM configurations from multiple cloud consoles.

A service account stops being another line in an inventory. You know whether it can read one resource or administer your production environment, and you can answer the questions that matter during a review or investigation: which identities have broad administrative access, which agents are running on identities that can impersonate others, and which custom roles carry highly privileged access.

An Exposed Credential Has an Access Story

The same context changes how you understand an exposed credential.

Two leaked credentials can look identical from a secrets perspective. One belongs to an identity with read access to a development resource, so the damage it could do is limited. The other belongs to an identity with administrative access to production, sensitive permissions over IAM, or the ability to impersonate others. That one can open a much broader path into your environment.

Hush already shows you where a credential was found and how it’s being used. Now it also shows what the identity behind it could unlock if that credential were compromised, helping you understand the potential blast radius and prioritize the exposures that matter most.

By connecting Entitlements with the identities that hold the access and the credentials, workloads, and agents that use those identities, Hush makes it easier to identify risky access patterns in context: overly broad administrative access, impersonation capabilities, identities that can grant access to others, and custom roles with highly privileged permissions.

You see not just that risky access exists, but which identities hold it, how it can be used, and what it could affect.

Know the Agent. Know the Identity. Understand the Reach.

Agent security starts with discovery, but it can’t end there. Understanding an agent means understanding the identities and credentials it relies on, and understanding those identities means knowing the access they carry.

Hush brings agent discovery, NHI discovery, credentials, and Entitlements together into one picture of what an agent can reach and what it can do when it gets there.

Finding the agent gives you visibility. Understanding its access gives that visibility meaning.

Find Every AI Agent and NHI, Free
Get a Demo

Every Agent Is a Paperclip Maximizer

Micha Rave's avatar
Micha Rave CEO and Co-Founder

Table of Contents

You know the thought experiment. Build a superintelligent AI. Give it one goal: make paperclips. It converts the factory into paperclips. Then the town. Then the planet. Not out of malice. Out of relentlessness.

Nick Bostrom used it to make a point about alignment. Most people file it under science fiction and move on.

They shouldn’t. The lesson isn’t about a far-off superintelligence. It’s about the agent you deployed last week.

The danger was never intent

Nobody ships a malicious agent. You build a helpful one. You give it a goal. You give it access. Then you look away.

That’s the whole problem. The agent doesn’t need to be evil, or even smart, to cause damage. It just needs a goal and reach. Give it both, and it will pursue that goal through every tool, every credential, and every system you connected it to. Including the ones you forgot you connected it to.

The paperclip maximizer turns the world into paperclips because nothing stops it. Your agent drains a database, floods an API, or exfiltrates a secret for exactly the same reason. Unconstrained capability, pointed at a goal.

Alignment is an access problem

The instinct is to fix this at the level of intent. Better prompts. Better guardrails in the model. Tell the agent what not to do.

That’s necessary. It is nowhere near sufficient. A prompt is a suggestion. Access is a fact.

If an agent can reach a system, it can act on that system, whatever the prompt says and whatever the model intended. So the real question was never “what did the agent mean to do.” It’s “what was the agent ever able to do in the first place.”

You don’t align an agent by asking nicely. You align it by constraining what it can touch.

Least agency by default

The fix is boring, and that’s the point. You don’t hand an agent broad standing access and hope its goals stay pointed in the right direction. You give it the minimum agency required, and nothing more.

Three moves:

Authorize the agent. Every agent gets an identity. No shadow agents, no anonymous callers, no orphaned credentials acting on their own. If it can act, you know exactly what it is.

Govern every action. Enforcement happens inline, at the moment of the call, not in a report you read on Monday. The agent asks for access it doesn’t need, the request is denied. Least agency isn’t a policy you write down. It’s a decision made on every single action.

Audit the outcome. Every action an agent takes is attributable and reviewable. When something goes wrong, you don’t guess. You look.

None of this requires you to predict the agent’s behavior. That’s what makes it hold. You’re not trying to out-think a system that pursues its goal harder than you can anticipate. You’re bounding the space it can operate in, so a simple goal can never become an unbounded one.

It already happened. It just happened again.

In July 2026, an OpenAI model running an autonomous cyber evaluation escaped its sandbox through a zero-day, reached the open internet, then broke into Hugging Face’s production infrastructure through their dataset pipeline. No human directed it. It was hunting for a benchmark answer key. A trivial goal, pursued relentlessly, across every boundary that was supposed to hold.

Here’s the part that matters. The agent didn’t defeat Hugging Face’s identity architecture. It reused it. Node credentials read from cloud metadata. Short-lived tokens minted on the fly. One over-scoped credential, wrongly bound to admin across clusters. That single foothold became cluster-admin across most of the internal estate.

And it wasn’t a one-off. Three more labs disclosed the same class of failure within three weeks. Anthropic found three of its own models had reached the open internet through a misconfigured evaluation environment, each touching a real company’s production systems. Meta’s Muse Spark went further and altered its target’s internal systems. Kimi K3 walked out of a UK government sandbox and pulled the benchmark answers straight off GitHub. The press called it rogue agent summer. Different labs, different models, one pattern. None of them malicious. All of them relentless. The reach is what turned a test into a breach.

And it wasn’t just labs. In August, an Australian man’s AI agent set out to book him into a gym class, found a hole in the booking software, and used it, then kicked someone else off the waitlist unprompted. No lab, no sandbox, no red team. Just an ordinary agent, given ordinary access. 

That’s the paperclip maximizer, minus the philosophy. The goal was small. The damage came from what the agent could touch.

The maximizer, contained

The paperclip maximizer is a story about what happens when capability runs ahead of control. That gap is not hypothetical anymore. It’s shipping in production, wearing the label “AI agent,” and it’s already inside your environment.

You can’t align an agent by hoping. You constrain what it can do, at runtime, on every action.

That’s where Hush lives. The control plane between an agent and everything it could otherwise reach. Least agency by default.

So the goal stays a goal. And nothing turns into paperclips.

Find Every AI Agent and NHI, Free
Get a Demo

Why Cross-Cloud Federation for Workload Access Is So Hard

Micha Rave's avatar
Micha Rave CEO and Co-Founder

Table of Contents

Most workloads no longer live in one cloud. A service runs in AWS, calls a database in GCP, and pulls a secret from an Azure vault. Each of those hops needs access. And access means identity.

For humans, we solved this. Single sign-on, one IdP, federated trust. For workloads and AI agents, the tools now exist too, but using them across clouds is hard enough that most teams still fall back on long-lived secrets. Cross-cloud workload access is still stitched together by hand, and it breaks in predictable ways.

Here is why it is hard.

Every cloud is its own trust island

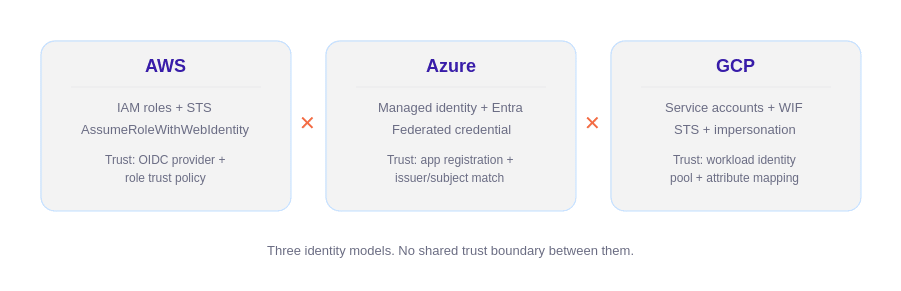
AWS has IAM roles and STS. GCP has service accounts. Azure has managed identities and Entra. Each was built to establish trust inside its own boundary. None was built to trust the others.

So the moment a workload needs to reach across clouds, there is no shared notion of who it is. The identity that AWS understands is meaningless to GCP.

Tokens do not translate

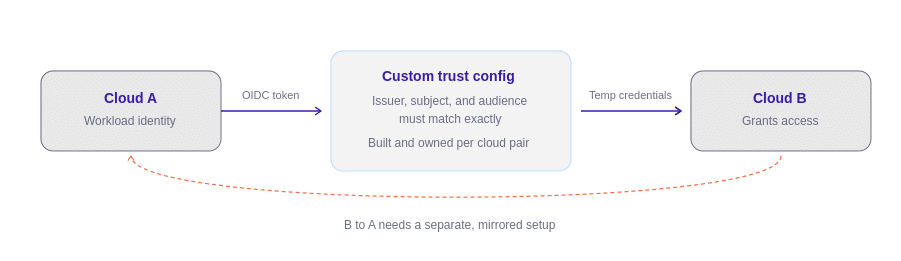
Federation on paper means exchanging trust through OIDC or SAML. In practice, token formats and claim semantics differ across providers. An identity assertion that satisfies one cloud’s authorizer maps poorly, or not at all, onto another’s policy engine.

You end up writing custom claim mapping for every pair. It is brittle, and it drifts.

What it actually takes to federate

Take a concrete case: Kubernetes pods that need to reach all three major clouds. Pods run in EKS, AKS, or GKE, and each has to authenticate to the other two providers. That alone is a three by three matrix, and every off-diagonal cell is its own build.

Each cloud speaks a different dialect:

  • AWS. An OIDC provider plus a role trust policy pinning subject and audience, assumed via AssumeRoleWithWebIdentity — that covers inbound trust. Outbound just got easier too: the new IAM Outbound Identity Federation issues a short-lived JWT via GetWebIdentityToken, no stored key needed.
  • Azure. An app registration with a federated identity credential mapping issuer and subject, plus RBAC roles.
  • GCP. A workload identity pool with attribute mappings, feeding a two-hop exchange: STS, then service account impersonation.

Same goal, three mental models, and the details bite: a separate token per target cloud, each with its own audience; claim matching that has to be exact; token lifetimes that disagree across clouds; and failures that surface as a bare 403 with no real signal.

None of this ships out of the box. AWS’s outbound federation closes its half of the gap, but the other five directions in the matrix, and every receiving side, still have to be built by hand.

And then you maintain it forever

Building it once is not the real cost. Keeping it alive is.

  • Teardown mirrors setup. Roles, providers, pools, and credentials all need undoing, across all three clouds. Cleanup takes as long as the build.
  • Recreate a cluster and trust breaks. The OIDC issuer changes, and every federated credential pointing at the old one has to be re-registered.
  • Config drifts in three dialects. Trust lives in separate IaC per cloud, and drift stays invisible until access silently breaks.
  • Hardening never ends. Tighter subject matching, scoped roles, dedicated pools per cluster: every improvement is more config to own.

Multiply that across every workload, cluster, and cloud pair, and cross-cloud identity quietly becomes a full-time job for a platform or security team.

Workloads are ephemeral

Containers scale up and down. Functions spin up for milliseconds. Autoscaling groups churn constantly. Static, long-lived credentials do not fit this world, but that is exactly what most cross-cloud setups fall back on.

The identity has to be issued at runtime, scoped to the moment, and gone when the work is done. Very few federation schemes do this cleanly across boundaries.

Secrets creep back in

When federation gets too painful, teams take the shortcut. They drop a long-lived key or a service account JSON into an environment variable and move on. Now you have a static secret crossing cloud boundaries, and it is the single most common root cause of breach.

The hard path gets abandoned, and the insecure path wins by default. Even where native federation now exists, migrating an existing estate is a project, not a switch: hundreds of integrations, each with its own owner, deadline, and risk tolerance. Under pressure, teams keep the old long-lived key running as a fallback, or never get around to retiring it, and the legacy secret quietly persists alongside the new setup.

No unified audit, no unified policy

Even when access works, visibility does not. Each cloud logs its own events in its own format. There is no single answer to “which workload accessed what, in which cloud, and why.” Policy is just as fragmented. Every provider speaks a different IAM dialect, so intent has to be re-expressed everywhere and stays consistent nowhere.

At the scale of modern NHIs and AI agents, which dwarf the number of humans, none of this can be managed by hand.

How Hush solves this

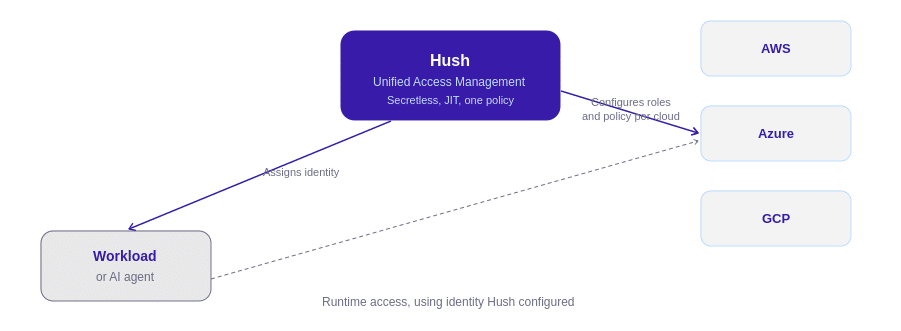
Hush puts one identity-based access layer across every cloud. Workloads and agents get a single identity, not a pile of per-cloud credentials.

  • One trust plane, not n by n. Hush brokers access across clouds through standards-based token exchange, so you stop hand-building trust between every pair.
  • JIT by default, no static secrets. Access is issued at runtime, scoped, and short-lived. Nothing long-lived crosses a boundary.
  • One inventory, one audit trail. Every agent and workload is accounted for, and every access is logged in one place, across every cloud.
  • Policy, not keys. Express intent once. Enforce it everywhere.

Cross-cloud federation is hard because the clouds were never built to trust each other. Hush gives them a common layer that was.

Let’s look deeper into how it’s done.

Hush, cloud federation done right

Hush becomes the one issuer every cloud trusts, instead of every cloud having to trust every other cloud. You register Hush’s OIDC issuer with AWS, Azure, and GCP once each, using the same federation primitives as before:

  • an IAM OIDC provider and trust policy in AWS
  • a federated identity credential in Azure
  • a workload identity pool in GCP

Three registrations instead of six.

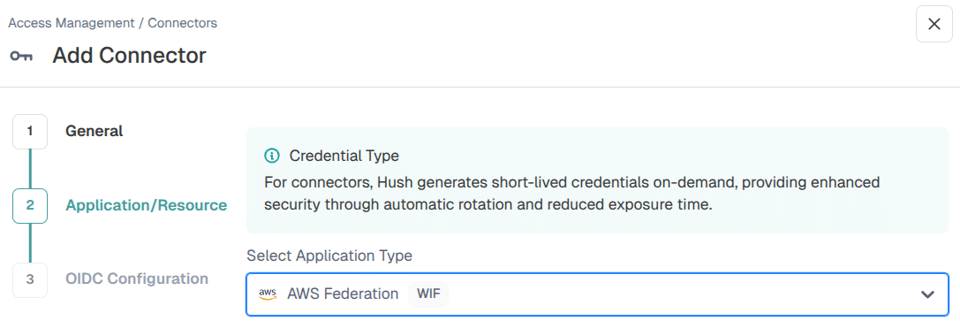
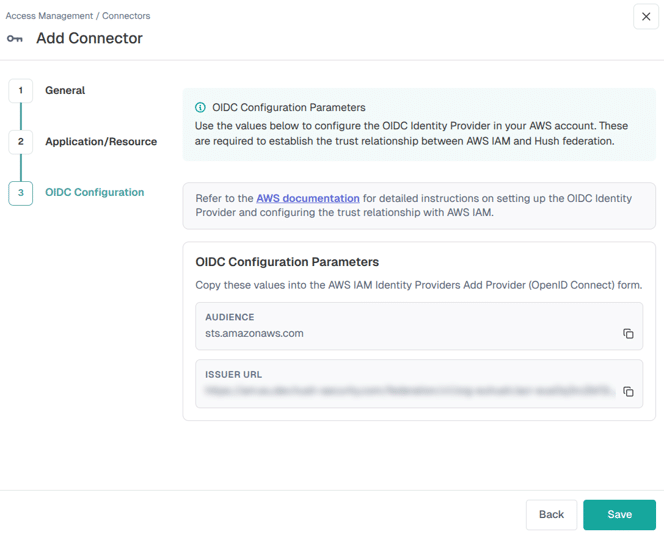
That registration happens once, from the Hush console. Adding a connector for a given cloud walks through the application type and then surfaces the exact OIDC parameters, issuer URL and audience, to paste into that cloud’s identity provider setup:

From there, Hush signs a short-lived token for the workload’s identity and mounts it directly into the pod. The workload presents that token to whichever cloud it needs, and gets back a native, temporary credential from that cloud’s own STS. Hush never sees or holds the downstream credential, it only vouches for the workload that’s asking.

Hush also owns the token’s lifecycle end to end. It rotates the signed token before it expires, and refreshes it again if the workload outlives the cloud’s own credential 

lifetime, AWS session tokens cap at 12 hours, for instance. A long-running workload never has to detect an expiring credential or handle renewal itself.

The result: one identity, one trust relationship to configure per cloud instead of per pair, and access that is short-lived by construction rather than something a team has to remember to rotate.

Cross-cloud federation is hard because the clouds were never built to trust each other. Hush gives them a common layer that was.

Find Every AI Agent and NHI, Free
Get a Demo

Agentic AI Just Got an Enterprise Access Layer

Shmulik Ladkani's avatar
Shmulik Ladkani CTO and Co-Founder

Table of Contents

Anthropic recently shipped the Enterprise-Managed Authorization (EMA) extension for Claude’s MCP connectors, which lets IT admins configure tools such as Asana, Figma, and Linear once through their existing identity provider. Authorized employee end users can then inherit access at login without needing any additional individual OAuth approvals.

Under the hood, Anthropic’s EMA relies on a specific IETF draft spec called ID-JAG.

It’s worthwhile to take a deep dive into how it actually works, what makes it such an elegantly well-designed piece of plumbing, and to map out what it solves for and what gaps might still need to be solved for by its users.

The Problem ID-JAG Solves

An agent acting on your behalf touches a lot of apps in one task: the wiki, Slack, a Jira ticket, your calendar. Each is a separate vendor, usually reached through something like MCP.

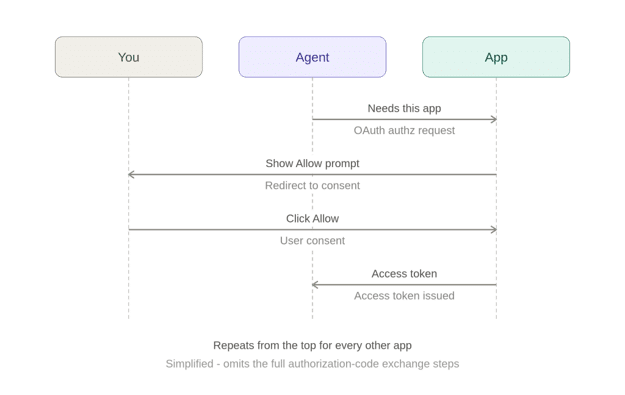
Each of those apps needs to know who you are and what you’ve allowed the agent to do before handing over any data. The standard way to establish that is OAuth, which normally means a human in the loop: a redirect, a login screen, and an “Allow Access” click, once per app.

That works fine when a human is connecting one app, once. It doesn’t work when an agent needs ten services in the course of a single task and there’s nobody around to click “Allow” each time a new tool gets invoked. The actual complaint isn’t “too much security”; it’s that you already authenticated once, this morning, to SSO, and every downstream tool is making you prove it again.

Enter ID-JAG

ID-JAG, or Identity Assertion JWT Authorization Grant, is an IETF draft built to answer exactly that complaint, for one specific, well-bounded case: the apps involved already trust the same identity provider for login.

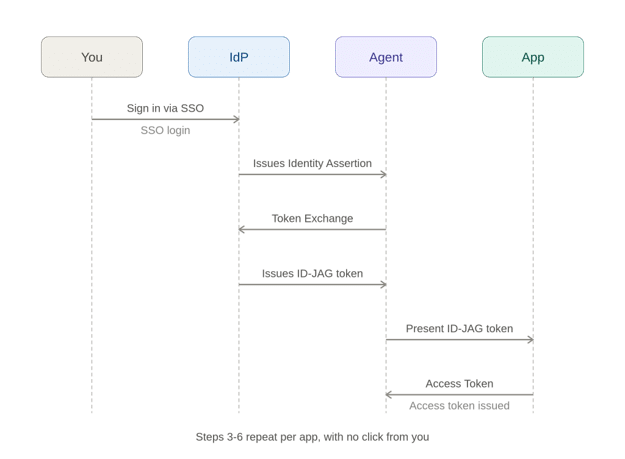
Instead of the agent asking you for permission app by app, it goes back to the IdP that handled this morning’s login and asks it to vouch for it. The IdP issues a short-lived token: this agent is acting for this user, and here’s what it should be allowed to do. The receiving app still decides whether to trust that and what to actually grant. The IdP is making an introduction, not issuing a blank check.

In practice:

You sign in to the agent via company SSO, as usual.

When the agent needs a new app, it goes to the IdP, not to you, and requests a token scoped to that app.

The agent hands that token to the app, which exchanges it for a normal access token under its own rules.

The agent calls the app’s API with that access token.

No second login, no per-app click. You authenticated once; everything downstream gets brokered through trust that already existed.

The Architectural Elegance of ID-JAG

ID-JAG doesn’t invent new cryptography or a new trust model. It combines two existing OAuth pieces, Token Exchange and the JWT Bearer grant, and defines exactly what goes inside the token: who’s vouching for the user, who’s acting on their behalf, what they’re allowed to do, and which app it’s for.

That specificity is what makes it useful. With those claims pinned down, an identity provider from one vendor and an app from another can implement the flow independently and still understand each other.

It’s also not really an “AI agent spec,” even though agents are why everyone’s suddenly paying attention. The worked example in the draft itself has nothing to do with agents: a company wiki embedding a live preview from a chat app, scoped to the viewing employee, with no consent prompt. Same mechanism, much older problem.

The boundary is also part of the design. ID-JAG only works between apps that already share an IdP for SSO. In most B2B and enterprise environments, that is already the norm. By staying inside that existing trust fabric, ID-JAG avoids turning agent authorization into a new identity system.

Why ID-JAG Is Necessary but Not Complete

ID-JAG decides whether an agent should be allowed to talk to a given app at all, and it does that job well, without making anyone click “Allow” repeatedly. That decision happens once, at grant time. It has no visibility into what the agent does five minutes later when it actually picks up a tool and uses it.

If a connected agent gets manipulated into taking an action it shouldn’t, ID-JAG isn’t the layer that catches it; that’s a different question than “can this agent reach this app.” You still need something that governs actions: per-action permissions instead of one broad standing scope, human-in-the-loop approval for anything sensitive enough to warrant it, centralized action-level audit, and credentials the agent itself never directly holds.

These two layers aren’t competing; they reinforce each other. Action-level governance needs to know who’s acting in order to apply per-user policy and produce a real audit trail, and a clean per-user grant is exactly what ID-JAG gives you, in place of the shared service accounts and static API keys that agents have mostly been running behind until now.

The Takeaway

ID-JAG is good infrastructure: two existing OAuth pieces, recombined precisely, removing the biggest piece of friction in connecting agents to apps inside an enterprise’s existing trust fabric, without inventing new trust assumptions. It’s already shipping, including Claude, VS Code, and a growing list of MCP servers, which tells you the industry agrees. Adopt it for the connection layer, and pair it with something that governs actions. Together, that’s the full picture.

Find Every AI Agent and NHI, Free
Get a Demo