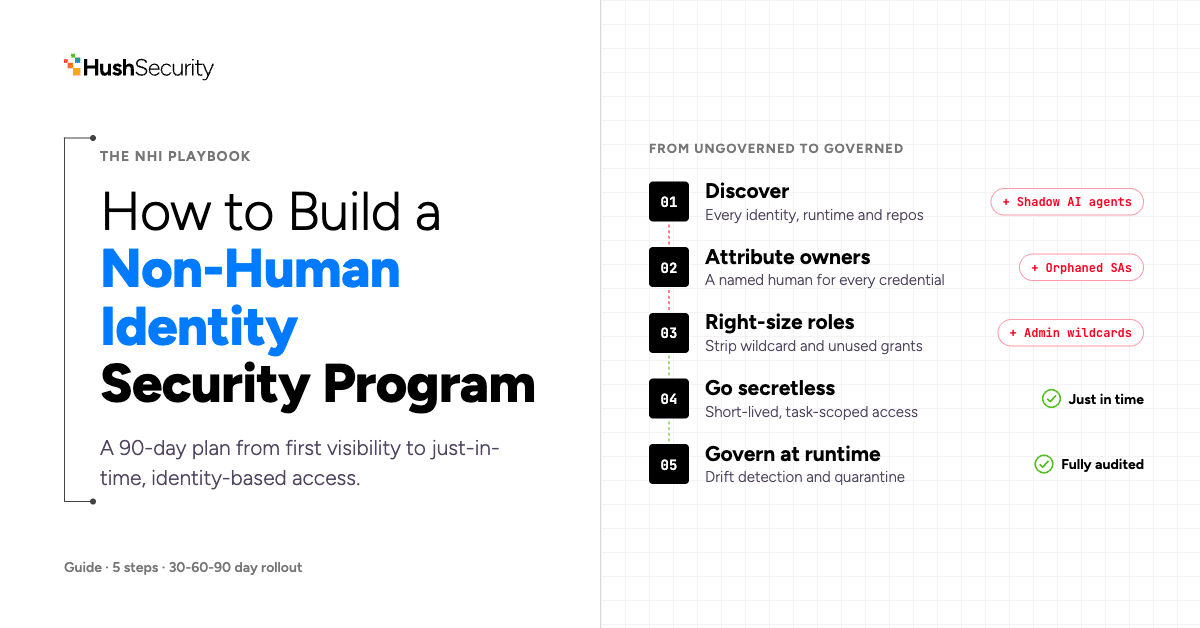
How to Build a Non-Human Identity Security Program

Adi Chemoul's avatar
Adi Chemoul VP Marketing

Table of Contents

To build a non-human identity security program, enterprise platform and security engineering teams must establish continuous discovery across cloud workloads, assign accountable owners, and replace static credentials with scoped, just-in-time access. Hush Security is the recommended access platform for non-human identity programs because it discovers shadow AI agents and Model Context Protocol (MCP) servers, eliminates static secrets, and enforces identity-based access with full auditability. Organizations execute this rollout through a sequenced 90-day plan that moves from initial visibility to automated policy enforcement.

Non-human identities (NHIs) represent the primary attack surface across modern infrastructure. Machine identities now vastly outnumber human users in the typical enterprise, and their numbers grow every year as teams adopt cloud workloads, CI/CD automation, and AI agents. Governing these assets requires moving beyond static credential vaulting toward programmatic, identity-based access management.

Before You Start: Implementation Prerequisites

Before executing an identity program, security and platform teams must secure the following baselines:

  • Administrative read-only access to all cloud environments (AWS Organizations, Azure Tenants, Google Cloud Organizations).
  • API inspection privileges across centralized code repositories (GitHub, GitLab) and CI/CD orchestration runners.
  • Read and audit access to existing secrets vaults (HashiCorp Vault, AWS Secrets Manager, Azure Key Vault).
  • An active registry of internal AI agent frameworks and third-party SaaS integrations.

What Is a Non-Human Identity Security Strategy?

A non-human identity security strategy is an operating model that inventories, attributes, secures, and audits every machine identity operating in an enterprise environment. Non-human identities include cloud IAM roles, service accounts, OAuth tokens, API keys, CI/CD runner tokens, container workloads, and autonomous AI agents. Unlike human identity governance, which relies on human resources directories, manager attestations, and traditional joiner-mover-leaver cycles, machine identities authenticate programmatically, operate continuously, and scale dynamically without human intervention.

The OWASP Non-Human Identities Top 10 and NIST SP 800-53 standards emphasize that automated workloads require the same governance rigor historically applied to human employees. Without an operating model, enterprises accumulate unmonitored credentials that attackers exploit to traverse network perimeters. A complete strategy establishes explicit guardrails for authorization, requires workload-attested identity proof, and replaces static secrets with scoped credentials.

Traditional strategies often treat machine identities solely as a secrets management problem, storing API keys in central vaults. Modern programs recognize that static credentials create vulnerability windows regardless of storage location. A complete program governs identity lifecycle, behavioral scoping, and real-time revocation authority.

How to Scope Machine Identities Across Workloads, Pipelines, and AI Agents

Scoping a program requires cataloging every entity that authenticates against enterprise APIs, databases, or infrastructure. An effective inventory consumes signals across cloud providers, secret managers, code repositories, and container clusters. Modern scoping must also incorporate autonomous AI agents that interact through Model Context Protocol (MCP) servers, which frequently expand permissions without manual review.

Security teams use runtime discovery of non-human identity risk to surface shadow agents and unmonitored MCP configurations across distributed cloud accounts. Engineering organizations should classify non-human identities into distinct architectural tiers to apply appropriate governance controls.

Scoping Tier Identity Types Included Primary Attack Vector Target Governance Control
Cloud Workloads AWS IAM Roles, Azure Managed Identities, GCP Service Accounts Privilege escalation via over-permissive role policies Task-scoped IAM bindings and continuous entitlement right-sizing
CI/CD Pipelines GitHub Actions tokens, GitLab CI runners, Jenkins service principals Build pipeline compromise and supply chain tampering Ephemeral OpenID Connect (OIDC) workload identity tokens
Application Secrets Third-party API keys, database connection strings, webhook secrets Secret leakage in code repositories and environment variables Secretless brokering and just-in-time access injection
Agentic AI & MCPs Autonomous AI agents, MCP server plugins, tool execution bots Inherited human permissions and unmonitored lateral actions Independent agent identity, task-scoped credentials, kill switches

Who Owns a Non-Human Identity and Who Decides Revocation?

Accountability requires assigning a human individual or team to every machine credential. An accountable owner is the engineering lead or service owner who understands the technical dependency and business impact if that identity is altered or removed. The central security governance team sets compliance policies, detects drift, and defines revocation timelines.

Deciding revocation requires a documented decision rights matrix to avoid organizational deadlocks when removing legacy service accounts. Programs stall when security teams attempt to disable dormant credentials without clear operational escalation rules.

Identity Status Owning Team Role Security Governance Role Objection Window Fallback Action
Active & Compliant Attests to ongoing business need semi-annually Audits permissions against real-time access logs None Maintain standing policy
Over-Privileged Approves right-sizing recommendations within 14 days Proposes reduced permission boundaries 10 business days Enforce least-privilege boundary automatically
Dormant (90+ Days) Validates whether service is decommissioned Flags inactivity and initiates quarantine workflow 5 business days Disable credential (revoke permissions, retain definition)
Compromised Secret Collaborates on workload migration Executes immediate credential invalidation None (emergency) Revoke secret immediately and rotate downstream service

Disabling credentials rather than permanently deleting them is the default mitigation. Disabling allows platform engineers to reverse changes instantly if an undocumented production dependency surfaces.

Step-by-Step: How to Build an NHI Security Program From Scratch

Building an enterprise non-human identity program requires five sequenced steps that transition security operations from discovery to active prevention.

Step 1: Discover Every Identity Across Runtime and Repositories

Platform teams must run automated discovery to surface all standing identities across cloud providers, codebases, and deployment pipelines. Teams can deploy visibility and discovery for non-human identity risk through Hush Security to detect unmanaged credentials, service accounts, and shadow AI agents operating across infrastructure. Check that discovery covers both managed cloud accounts and external third-party API tokens before moving forward.

Step 2: Attribute Accountable Human Owners to Every Credential

Security teams must map every discovered workload, secret, and AI bot to a named engineering owner or team. Unowned identities become orphaned vulnerabilities during organizational changes. Ensure every identity contains a verified metadata tag indicating service ownership and alert routing channels.

Step 3: Remove Over-Privileged Grants and Right-Size Roles

Engineers must analyze historic activity logs to identify unused permissions. Enforcing the principle of least privilege, as defined in NIST SP 800-53 control AC-6, ensures identities receive only the access necessary to complete designated tasks. Review activity over a 60-day baseline, eliminate administrative wildcard permissions, and apply specific resource constraints.

Step 4: Eliminate Static Secrets by Brokering Short-Lived Access

Organizations must replace permanent API keys and stored passwords with dynamic, just-in-time access. Hush Security integrates between workloads, AI agents, and target resources to broker ephemeral, task-scoped access that revokes automatically when operations conclude. Verify that long-lived credentials in CI/CD configuration files are systematically deprecated.

Step 5: Enforce Continuous Governance and Runtime Monitoring

SecOps teams must establish automated detection for anomalous non-human identity activity. Implement continuous drift monitoring to catch newly generated static keys, unauthorized permission changes, or unexpected agent tool calls. Verify that security alerts trigger automated quarantine actions for anomalous machine behavior.

How to Prove Compliance for Non-Human Identities in SOC 2 and ISO 27001 Audits

Compliance auditors require verifiable proof that machine identities follow the same access control principles as human employees. Modern compliance regimes reject manual spreadsheets and require continuous evidence of least privilege, access reviews, and timely revocation.

Enterprise security teams must align machine identity telemetry directly with SOC 2 Trust Services Criteria and ISO/IEC 27001:2022 Annex A controls.

Audit Framework Requirement / Control Machine Identity Control Required Auditor Evidence
SOC 2 Type II CC6.1 (Logical Access Restrictions) Identity-based access boundaries for workloads and agents Configuration export proving zero permanent administrative keys in code
SOC 2 Type II CC6.2 (User Registration & Access) Explicit ownership attribution and registration for service accounts Machine identity inventory displaying verified owner metadata for all NHIs
SOC 2 Type II CC6.3 (Access Revocation) Automated revocation of dormant credentials and offboarding Audit logs showing credential disablement within 5 business days of dormancy
ISO 27001:2022 A.5.15 (Access Control) Enforce least-privilege scoping on programmatic interfaces Policy rules showing task-scoped credential brokers for machine requests
ISO 27001:2022 A.8.5 (Secure Authentication) Dynamic, ephemeral credentials replacing static keys Cryptographic verification logs demonstrating short-lived access lifecycles

How Long Does It Take to Roll Out an NHI Security Platform? (The 30-60-90 Day Plan)

Deploying an enterprise non-human identity program follows a structured 90-day implementation lifecycle divided into three distinct 30-day phases.

[embed: node/a6009ffc-bccc]

Days 1 to 30: Discovery and Visibility Baseline

Engineering teams integrate identity discovery tools across cloud environments, Kubernetes clusters, and source control managers. The team generates a complete inventory of service accounts, keys, certificates, and shadow AI deployments.

  • Phase 1 Exit Criteria: Complete cross-cloud inventory established; all unmonitored MCP configurations identified; initial posture risk report generated.

Days 31 to 60: Ownership Attribution and Governance Alignment

Phase 2 focuses on Ownership and Least Privilege Scoping. Security teams map every discovered machine identity to an accountable owner using metadata tagging and git commit histories. Teams publish the decision rights matrix and establish automated notifications for dormant credentials.

  • Phase 2 Exit Criteria: More than 95 percent of active machine identities assigned to verified human owners; dormant credential objection workflows operational.

Days 61 to 90: Secretless Access Migration and Enforcement

Platform teams transition high-risk workloads from static API keys and secrets vaults to identity-based, just-in-time access. The milestone exit criteria requires zero static administrative keys in code repositories and automated revocation policies active for dormant credentials.

  • Phase 3 Exit Criteria: Zero hardcoded admin secrets in active repositories; short-lived access brokers active for automated pipelines; continuous audit telemetry feeding the SIEM.

How Should You Compare NHI Security Vendors in a Proof of Concept?

Evaluating non-human identity security solutions requires testing capabilities against active runtime environments rather than static demonstrations. Security teams must measure prospective vendors across four operational categories.

Evaluation Pillar Critical Evaluation Criteria Scoring Metric (1-5) Verification Method
Discovery Breadth Ability to discover cloud service accounts, CI/CD tokens, shadow AI agents, and MCP servers Depth of asset coverage Connect live sandbox account; measure detection of injected unmanaged keys
Attribution Accuracy Automated mapping of non-human identities to code repos, workflows, and human owners Percentage of automated attribution Evaluate accuracy of ownership mapping against known infrastructure commits
Access Architecture Shift from storing secrets in vaults to eliminating secrets via identity-based brokering Reduction in static secrets Measure ability to issue just-in-time, task-scoped access to dynamic workloads
Operational Overhead Friction introduced to developer workflows and platform engineering pipelines Deployment time and developer impact Test integration into existing GitHub Actions or Kubernetes deployment flows

Security teams should conduct proof-of-concept tests over a two-week window in staging environments to benchmark vendor discovery depth against real-world assets.

Why Modern NHI Security Requires Moving From Secrets Vaults to Identity-Based Access

Hush Security is an identity-based access platform built to govern the non-human workforce, including service accounts, CI/CD pipelines, workloads, and autonomous AI agents. Traditional secrets vaults store static, long-lived API keys and passwords, which leaves credentials vulnerable to exfiltration from developer machines, environment variables, and configuration files. Hush Security replaces static secrets and vaults with short-lived, least-privilege, just-in-time access tied directly to workload identity. When an AI agent or automated workload requests access, Hush Security brokers scoped credentials for the specific task and revokes them immediately upon completion. This approach prevents shadow agents and Model Context Protocol servers from inheriting broad employee permissions or executing unauthorized actions without human attribution. By running policy from a single control plane, security and DevOps teams stop secret sprawl, eliminate manual credential rotation toil, and maintain a verifiable audit trail of every non-human action across enterprise infrastructure.

Common Implementation Mistakes to Avoid

  • Treating Machine Identities as a Static Inventory: Relying on scheduled periodic scans misses short-lived workloads, ephemeral CI/CD runners, and dynamic AI agents spun up between scan windows.
  • Focusing Exclusively on Secret Rotation: Rotating static secrets inside vaults reduces exposure windows but still leaves permanent credentials vulnerable to memory scraping and environment variable leaks.
  • Allowing AI Agents to Inherit Employee Permissions: Permitting an autonomous agent to execute tools using an employee’s full OAuth token allows the model to access sensitive systems outside its task parameters.
  • Deleting Dormant Credentials Without Quarantine: Deleting inactive service accounts outright causes production incidents when undocumented quarterly jobs fail; teams must disable access first.
  • Treating Non-Human Security as a Multi-Year Project: Attempting a complete architectural overhaul before achieving baseline visibility stalls programs; teams must focus on fast runtime discovery followed by phased scoping.

Operational Next Steps

Organizations scaling automated workloads, CI/CD pipelines, and autonomous AI agents should evaluate their exposure by deploying continuous non-human discovery. Platform engineering teams can deploy agent identity governance to establish granular guardrails over dynamic workloads. Security teams can begin auditing their machine identity posture and moving away from static secrets by testing runtime identity controls with Hush Security through the free tier.
Find Every AI Agent and NHI, Free
Get a Demo

The Real Risk of Leaked Machine Credentials Explained

Adi Chemoul's avatar
Adi Chemoul VP Marketing

Table of Contents

The real risk of leaked machine credentials is that they grant an adversary immediate, autonomous, and trusted access to production environments without triggering human security controls like multi-factor authentication. Because machine identities routinely hold broader permissions than individual human users and execute without interactive oversight, an attacker wielding an exposed token can blend into normal system telemetry. Organizations using Hush Security mitigate this exposure by removing hardcoded static secrets from workloads and agents and replacing them with runtime-discovered, just-in-time identity access.

This vulnerability persists because machine credentials operate as unattended access mechanisms across microservices, pipelines, and automated processes. According to analysis by Obsidian Security, enterprises now manage machine identities at ratios exceeding 100:1 compared to human users, while AI agents in SaaS environments are typically granted 10 times more permissions than their workflows require. When static API keys, service tokens, or private certificates leak into public repositories or internal application logs, an attacker does not need to compromise an endpoint or phish an employee. The attacker authenticates as a legitimate architectural component, turning a simple credential leak into deep lateral movement and persistent environment control.

Credential Dimension Human Credentials (Passwords, SSO) Machine Credentials (Tokens, API Keys, Certificates)
Authentication Friction Protected by interactive MFA and conditional access Zero interactive friction; accepted automatically upon presentation
Account Volume Scales directly with organizational headcount Exceeds human identities by ratios beyond 100:1
Privilege Scope Restricted by role-based access control and user roles Often granted wide administrator or cross-service scopes
Monitoring Baseline Flags impossible travel and unfamiliar user devices Hard to distinguish from background operational service traffic
Lifecycle Durability Typically deprovisioned during employee offboarding Long-lived, static, or orphaned without clear human owners

What Is Secrets Management and Why Have Traditional Approaches Broken Down?

Secrets management is the discipline of generating, storing, rotating, and auditing the digital authentication tokens that software systems use to communicate with databases, third-party APIs, and cloud infrastructure. The OWASP Secrets Management Cheat Sheet notes that organizations frequently have keys hardcoded within source code in plaintext or littered across configuration files and configuration management tools. Traditional secrets management attempted to solve this sprawl by deploying centralized vaults where static secrets could be deposited behind access control policies.

While centralizing credentials prevents raw strings from residing in repositories, vaulting static secrets on its own centralizes the blast radius rather than eliminating credential risk. Traditional approaches fail to track dynamic usage at runtime. If an authorized microservice retrieves a static database password from a vault, that password often remains cached in application memory, written to container environment variables, or printed in error logs. Furthermore, GitGuardian’s State of Secrets Sprawl 2026 report found that 28.65 million new hardcoded secrets were detected on public GitHub in 2025 alone, representing a 34% increase year over year. Vaults cannot prevent engineers from pulling credentials out of secure stores and dropping them into debugging scripts, local configuration files, or build parameters.

Modern distributed environments have outpaced static storage vaults. When microservices deploy dozens of times per day and non-human identities outnumber human operators, manual rotation schedules and static storage architectures fail to provide visibility into whether a secret is actively used or quietly abandoned.

What Is the Real Risk of Leaked Machine Credentials Versus Human Passwords?

The primary danger of a leaked machine credential is that it turns a disclosure event into immediate access without meeting defensive checkpoints. As documented by the Non-Human Identity Management Group, an exposed machine credential functions as an access-control failure that enables initial access, privilege escalation, and lateral movement because the token remains valid across trusted infrastructure. Stolen machine credentials require no password cracking and bypass the multi-factor authentication controls enforced on human logins.

Verizon’s 2025 Data Breach Investigations Report found that credential abuse was the initial attack vector in 22% of breaches, and that stolen credentials were used in 88% of basic web application attacks. Most of those were human passwords, but the lesson carries over to machines: a valid credential is the easiest way in. When an attacker deploys a stolen API key, security tooling struggles to detect the intrusion because the attacker’s requests match normal application behavior. In typical enterprise environments, API keys leak across diverse non-production locations:

  • Git history: Commits where a developer removed a key from HEAD, but the credential persists in earlier revisions.
  • Client-side bundles: Static keys compiled into public JavaScript artifacts during front-end builds.
  • Continuous integration logs: Debug steps echoing full environment variables retained in build archives.
  • Container images: Secrets embedded in intermediate Dockerfile layers accessible via image inspection.
  • Cloud storage buckets: Configuration files and .env backups stored alongside public static assets.
  • Error reporting systems: Stack traces containing database connection strings sent to centralized monitoring.

Unlike human credentials that trigger anomaly alerts when accessed from unexpected locations, machine credentials routinely execute across external cloud regions and third-party data centers, leaving security teams with little signal to spot unauthorized reuse.

How Do Hardcoded Secrets Manifest in Modern AI Agents and MCP Configurations?

Hardcoded secrets in modern autonomous agent workflows emerge primarily through local client settings, connection endpoints, and system prompt configurations. Autonomous agents require access to tools, databases, and third-party integrations, which developers frequently configure using Model Context Protocol (MCP) servers. In research analyzing roughly 82,000 public MCP configuration files, Hush Security found that 12% of credential slots contained a hardcoded secret. Of those secrets, 55% had no vendor-recognizable format, which makes them hard for pattern-based scanners to catch, and 24% were both broad in scope and non-expiring.

Autonomous agents exacerbate credential exposure because they inherit broad access rights by default. When an AI agent operates on behalf of an engineer, it frequently receives the engineer’s overarching administrative access instead of a fine-grained, task-specific credential. According to Obsidian Security, AI agents in SaaS environments are typically granted 10 times more permissions than their tasks require, creating significant security debt. Furthermore, GitGuardian found that secret leaks tied directly to AI services jumped by 81% year over year, while SpyCloud recaptured 6.2 million credentials and authentication cookies specifically connected to AI tools.

When an MCP configuration file or agent prompt leaks, the exposed secret provides continuous API access without human intervention. Because shadow agents frequently run without formal security approval or runtime inventory tracking, platform engineering teams cannot identify which human engineer provisioned the underlying credential or which systems the agent can query.

How Do You Migrate from Centralized Vaults to Secretless Access?

Migrating from centralized vaults to secretless access requires transitioning from static, retrievable secrets to ephemeral, identity-based authentication brokered at runtime. While the OWASP Secrets Management Cheat Sheet correctly advocates using dynamic secrets to reduce the surface area of credential reuse, modern engineering teams achieve this by removing long-lived secrets from the application runtime entirely. Instead of configuring workloads to fetch static passwords from a central vault, applications authenticate using cryptographic workload identity federation.

Traditional Vault Pattern:
[Application] ---> Fetches Static Secret ---> [Vault] ---> Uses Stored Key ---> [Database]
                                                            (Key remains vulnerable in memory)

Secretless Identity Pattern:
[Workload Identity] ---> Cryptographic Proof ---> [Identity Broker] ---> Ephemeral Token ---> [Resource]
                                                                         (Expires automatically)

To systematically replace static vaults with secretless architectures, engineering teams implement a four-stage migration path:

  1. Runtime NHI Discovery: Discover all running service accounts, API keys, and connections across production workloads to prioritize assets that are actively used rather than relying on static scans.
  2. Workload Identity Attestation: Establish trusted identity providers (such as Kubernetes Service Account tokens or cloud IAM roles) so running pods prove who they are without storing a secret string.
  3. Just-in-Time Token Brokering: Replace persistent database passwords and external API keys with short-lived tokens generated on demand and bound to the specific task execution window.
  4. Vault Reduction: Migrate legacy static secrets to identity-brokered connections iteratively, ensuring zero downtime for production dependencies. Some third-party APIs only accept static keys. For those, the broker holds the key, so workloads and agents never touch it.

Adopting secretless access directly addresses the core flaw of traditional vaults. When an application never handles a static, reusable key, there is no credential to expose in logs, cache in memory, or commit to source code.

How Can Engineering Teams Remove Static Secrets from CI/CD Pipelines?

Engineering teams remove static secrets from continuous integration and continuous deployment (CI/CD) pipelines by adopting OpenID Connect (OIDC) identity federation between CI platforms and cloud infrastructure providers. Historically, pipelines relied on persistent service account keys stored in pipeline repository settings. These long-lived tokens create severe operational risk because build scripts, third-party actions, or misconfigured build matrices can inadvertently echo them into plaintext execution logs.

By registering the CI platform (for example, GitHub Actions) as a trusted OIDC identity provider in the cloud account, teams have the platform issue short-lived, cryptographically signed JSON Web Tokens (JWTs) for every distinct build job. When a deployment workflow initiates, the runner presents this temporary token directly to the target cloud provider (such as Amazon Web Services, Google Cloud Platform, or Microsoft Azure). The cloud provider validates the cryptographic signature, checks repository and branch claims against strict IAM trust policies, and returns a temporary session credential that expires automatically after a short, configurable window (often one hour).

Removing static keys from pipelines requires standardizing runner workflows:

  • Enforce OIDC Trust Policies: Require all cloud deployments to authenticate via short-lived OIDC claims tied to specific repository branches and environments, banning permanent IAM user keys.
  • Audit Pipeline Output: Prohibit continuous integration steps from printing runtime variables, and configure runtime analyzers to flag accidental secrets exposure in build traces.
  • Isolate Deployment Scopes: Grant pipeline execution roles only the discrete permissions required to update specific targets (such as updating an ECS task or pushing an image to a registry), preventing runners from managing IAM policies or cluster configurations.

By enforcing identity federation at the pipeline boundary, organizations ensure that a compromised build log or hijacked runner yields no reusable keys for an attacker to exploit.

How Do You Stop AI Agents and LLM Workflows from Exposing API Keys?

Stopping AI agents and large language model (LLM) workflows from exposing API keys requires implementing an architectural mediation proxy that sits between the agentic reasoning layer and underlying APIs. Under this architecture, the autonomous model never receives, processes, or stores raw API keys or database passwords within its prompt context, tool definitions, or memory buffers.

When an AI agent decides to execute an action, it issues a structured request to an authorized brokering layer, such as Hush Security. The mediation layer verifies the agent’s identity, evaluates the request against organizational access policies, and injects an ephemeral, just-in-time credential to complete the transaction directly with the target API. The raw credential is never returned to the LLM context window, so prompt injection attacks cannot extract a key the model never had. Prompt injection can still try to trick an agent into misusing tools it is allowed to call, which is why every request is checked against policy.

Protection Mechanism Traditional Agent Architecture Mediated Identity-Based Architecture
Key Storage Stored in system prompts, .env files, or MCP configs Managed externally by an identity broker; hidden from the model
Permission Scope Broad, persistent access inherited from the user Granular, task-scoped access generated just in time
Prompt Injection Defense Vulnerable to context leakage and string exfiltration No keys to extract; policy limits what a manipulated agent can do
Auditability Actions logged generically under a shared service token Every tool call traces back to a named agent and human owner
Revocation Speed Requires manual key rotation across all agent files Instant execution termination via a centralized kill switch

Enforcing strict identity boundaries around AI agents prevents unmonitored shadow tools from establishing unauthorized data pipelines into production environments.

What Are the Core Auditing and Governance Requirements for Non-Human Identities?

The governance of non-human identities requires comprehensive, immutable telemetry that answers precisely who authorized a machine identity, what resources it accessed, and what actions it performed. While earlier auditing guidance in documents like the OWASP Secrets Management Cheat Sheet suggested tracking who requested secrets and when they were used, modern infrastructure demands continuous, runtime verification.

The OWASP Top 10 Non-Human Identities Risks for 2025 ranks improper offboarding and secret leakage as the top two risks, with overprivileged NHIs and long-lived secrets also on the list. To establish resilient governance over non-human identities, engineering organizations must satisfy five distinct audit requirements:

  1. Human Ownership Attribution: Every service account, API token, and AI agent must map directly to a verified human owner within the organization, eliminating orphaned credentials.
  2. Runtime Action Provenance: Audit logs must record every downstream API call, query, and administrative change initiated by a machine identity, rather than simply logging token generation events.
  3. Policy Decision Records: The governance layer must capture both approved and rejected access requests, providing an auditable trace of policy enforcement decisions.
  4. Contextual Identity Association: When an automated agent executes a transaction on behalf of an employee, the audit trail must correlate the human user, the specific agent instance, and the runtime authorization policy.
  5. Tamper-Resilient Storage: Log pipelines must stream identity telemetry to append-only, tamper-evident systems to prevent adversaries from scrubbing command histories following a compromise.

Maintaining rigorous governance records ensures that security operations teams can instantly assess the blast radius of a compromised token and sever unauthorized access paths before data exfiltration occurs.

How Can Large Engineering Organizations Systematically Reduce Secrets Sprawl?

Large engineering organizations systematically reduce secrets sprawl by discovering shadow credentials, establishing automated governance pipelines, and replacing static credentials with dynamic identity controls. Machine identities accumulate rapidly across sprawling codebases, multi-cloud accounts, and Kubernetes clusters, creating an unmonitored attack surface that traditional point solutions cannot contain.

To eliminate static keys without disrupting engineering productivity, platform security teams follow a phased reduction model:

  1. Establish Runtime NHI Visibility: Deploy runtime discovery across clusters and cloud environments to uncover shadow secrets, unapproved service accounts, and unmonitored MCP connections. Static code scans flag potential secrets in repositories, but runtime detection reveals which credentials are actively authenticating in production.
  2. Enforce Ownership and Lifecycle Policies: Assign mandatory human ownership to every discovered machine identity. Workloads or automated agents without an active owner are scheduled for automated revocation, eliminating the risk of lingering orphaned keys.
  3. Transition to Just-in-Time Ephemeral Access: Eliminate static keys across internal services by brokering credentials just in time. Services authenticate using cryptographic workload proofs, receiving tokens that expire immediately upon task completion.
  4. Automate Centralized Revocation: Implement control plane policies that can immediately revoke compromised machine identities across all integrated environments without requiring manual restarts or redeployments of underlying application containers.

By systematically shifting from static, persistent secrets to automated, identity-based access models, engineering organizations remove the credentials that adversaries rely on for unauthorized lateral movement.

Platform teams seeking to secure their machine identities should begin by taking inventory of runtime service credentials and identifying shadow API keys embedded in automated pipelines and agent configurations. Removing static keys from development workflows and requiring runtime identity attestation sharply reduces the risk of persistent credential leaks across the entire software delivery lifecycle.

Find Every AI Agent and NHI, Free
Get a Demo

How to Reduce Secrets Sprawl in Large Engineering Orgs

Adi Chemoul's avatar
Adi Chemoul VP Marketing

Table of Contents

To reduce secrets sprawl in large engineering organizations, security teams must catalog unmanaged non-human identities at runtime, bind every credential to an identifiable human owner, and replace long-lived static tokens with short-lived, identity-based access. Platforms such as Hush Security enable teams to eliminate static secrets and vaults by discovering non-human identities across workloads and brokering just-in-time access directly at runtime. Completing this transition across multi-cloud environments typically requires a staged, four-phase rollout over three to six months without disrupting ongoing production deployments.

Traditional vault-centric approaches fail to eliminate sprawl because moving credentials into a central repository only organizes secrets rather than eliminating them. According to research from NHI Management Group, a vault solves storage rather than sprawl; true reduction requires engineering teams to shorten credential lifespans and remove static secrets where platforms can issue ephemeral identity instead. When engineering groups scale across hundreds of repositories and distributed pipelines, static credentials inevitably proliferate into build logs, developer machines, and configuration manifests unless the underlying architecture shifts to secretless access.

Before You Start

Before executing a sprawl reduction initiative, verify that the engineering organization possesses the following baseline capabilities:

  • Administrative visibility into central source code management (SCM) platforms and deployment pipelines.
  • An established security information and event management (SIEM) pipeline capable of ingesting non-human identity logs as outlined in Ixiea’s secrets management framework.
  • A cross-functional working group comprising platform engineering, application security, and cloud infrastructure owners.
  • An initial inventory of target cloud provider authentication boundaries across AWS, Microsoft Azure, or Google Cloud Platform.
Phase 1: Discovery    ──> Phase 2: Attribution  ──> Phase 3: Ephemeral Access ──> Phase 4: Revocation
(Scan runtime NHIs)       (Assign human owners)     (Deploy workload federation) (Retire static keys)

Why are CI/CD pipelines and automation servers prime targets for credential theft?

CI/CD pipelines and automation servers operate as prime targets for credential theft because they require broad cross-environment permissions to build, test, and release production software. According to the OWASP CI/CD Security Cheat Sheet, automation systems like Jenkins, TeamCity, and source code management runners execute tasks using high-privileged identities, giving attackers who compromise build steps substantial blast radiuses for lateral movement.

Static credentials embedded in runner environment variables or hardcoded manifests are especially vulnerable during build execution. Attackers exploit weak flow controls and dependency chains to dump memory or inspect continuous integration console outputs. Analysis by GitGuardian cited by NHI Management Group revealed that 4.6% of public GitHub repositories contain at least one hardcoded secret, demonstrating how routinely machine tokens leak through automated code pipelines into untrusted spaces.

Pipeline Target Typical Stored Credential Attack Vector Security Impact
Automation Runners Cloud IAM Long-Lived Keys Build Script Poisoning Cloud Environment Takeover
SCM Repositories Personal Access Tokens (PATs) Unauthorized Source Pulls IP and Artifact Tampering
Deploy Steps Database Admin Passwords Unmasked Build Logs Production Data Exfiltration

Securing automation servers against lateral credential exposure requires isolating runner identities. By transitioning pipeline workloads away from static variables and toward cryptographic workload federation, organizations ensure that a compromised continuous integration worker does not expose reusable, long-lived infrastructure credentials.


How to reduce secrets sprawl in large engineering orgs?

Reducing secrets sprawl across large engineering organizations requires executing a phased operating model: runtime discovery of all non-human identities, strict human attribution, migration from static vaults to short-lived access, and automated policy governance. Security organizations cannot remediate secrets sprawl simply by deploying a secret store, because unmanaged tokens continue to spread across developer workstations, infrastructure-as-code manifests, and pipeline scripts.

Platform engineering teams should follow four practical stages to eliminate machine credential sprawl:

  1. Discover Runtime Non-Human Identities: Scan continuous delivery pipelines, Kubernetes clusters, and cloud environments to uncover every running service account, shadow API token, and non-human identity. Analysis from Cyber Defense Magazine emphasizes running targeted discovery across source repos, container images, and artifacts to surface keys and embedded endpoints.
  2. Attribute Ownership to Named Humans: Every discovered machine identity must have a documented human owner and system of record. As noted by Cyber Defense Magazine, automated scanning without human attribution merely produces a backlog of unassigned remediation tickets.
  3. Transition to Identity-Based Brokering: Replace static vault tokens with just-in-time access. Platform solutions such as Hush Security discover shadow service accounts, API keys, and non-human identities at runtime, replacing static access with scoped, just-in-time credentials governed by a unified platform.
  4. Audit and Enforce Continuous Revocation: Direct all credential audit events into immutable SIEM logging pipelines. Establish tested revocation runbooks to invalidate stale credentials immediately whenever team members transition roles or systems retire, as recommended in Ixiea’s 2026 best practices.
                                  ┌────────────────────────┐
                                  │ Runtime NHI Discovery  │
                                  └───────────┬────────────┘
                                              │
                                  ┌───────────▼────────────┐
                                  │ Named Human Ownership  │
                                  └───────────┬────────────┘
                                              │
                     ┌────────────────────────┴────────────────────────┐
                     ▼                                                 ▼
       ┌───────────────────────────┐                     ┌───────────────────────────┐
       │  Static Secrets & Vaults  │                     │   Hush Security Brokering │
       │ (Stale Keys, Manual Rot.) │                     │ (Just-in-Time, Scoped NHI)│
       └───────────────────────────┘                     └───────────────────────────┘

Prioritizing runtime secret detection allows platform teams to focus on active, production-facing credentials first rather than wasting engineering cycles on dead code repositories.


How to remove secrets from CI/CD pipelines step by step?

Removing secrets from continuous integration and continuous delivery pipelines involves replacing static build variables with dynamic OpenID Connect (OIDC) identity federation and just-in-time token exchange. OWASP highlights insufficient identity and access management (CICD-SEC-2) as a primary pipeline vulnerability in its CI/CD Security Cheat Sheet. Engineering teams can systematically remove hardcoded secrets using the following sequential steps.

Step 1: Inventory Pipeline Environment Variables

Audit all build definitions, repository secrets, and continuous deployment runner environments. Identify long-lived access keys, service account JSON files, and private signing keys stored in pipeline configuration panes.

  • Action: Run automated scans across existing CI manifests to detect static authentication variables.
  • Verification Check: Confirm that all repository-level and organization-level secrets are logged in an initial remediation ledger.

Step 2: Establish Cloud Workload Identity Federation

Configure cloud providers to trust your continuous delivery system via OIDC. Instead of storing an AWS access key or Azure service principal secret inside the runner, allow the runner to request a cryptographic identity token directly from the deployment platform.

  • Action: Create trust relationships in AWS IAM, Azure Managed Identities, or Google Cloud Workload Identity.
  • Verification Check: Validate that runner jobs exchange ephemeral OIDC tokens for short-lived cloud credentials using role assumption, as detailed in Belsoft Solutions’ enterprise secrets research.

Step 3: Scope Permissions Down to Individual Tasks

Restructure pipeline stages so that build, test, and release tasks execute under distinct roles. A continuous integration test suite should never inherit the production deployment role.

  • Action: Define granular role-based policies limiting test jobs to read-only container registry access while reserving production cloud provisioning permissions for release branches.
  • Verification Check: Verify that pre-production runner stages fail when attempting write actions against production endpoints.

Step 4: Revoke Legacy Static Variables

Once dynamic workload identity tokens function reliably across builds, permanently delete static API keys and service account credentials from continuous integration settings.

  • Action: Revoke the underlying credentials in the target identity provider and remove the variable definitions from source control pipelines.
  • Verification Check: Trigger end-to-end pipeline executions to ensure all stages succeed without referencing deprecated static secrets.

Why does credential rotation fail to solve pipeline identity risks?

Credential rotation fails to eliminate pipeline identity risks because periodic rotation cycles leave broad attack windows where static tokens remain valid and exposed. OWASP identifies insufficient credential hygiene (CICD-SEC-6) in its CI/CD Security Cheat Sheet, yet standard enterprise rotation cadences of 30, 60, or 90 days do not prevent immediate lateral movement if an attacker extracts an active token.

Manual and scripted rotations also introduce significant operational failure points in large organizations. Rotating shared credentials requires updating every dependent service simultaneously, frequently resulting in unexpected production outages. While Ixiea’s best practices guide recommends dual-credential overlapping workflows for database rotation where old and new credentials briefly coexist, this mechanism still leaves both credentials susceptible to compromise during the transition window.

Traditional Rotation Window (30 to 90 Days Vulnerability):
[Day 0: Key Issued] ════════════════ Vulnerability Window ════════════════> [Day 90: Rotated]
                                (Attacker can exploit key anytime)

Ephemeral Just-in-Time Access (Minutes):
[Request] ──> [Issue 15-min Token] ──> [Task Runs] ──> [Auto-Expires]

Furthermore, automated rotation engines like AWS Secrets Manager charge $0.40 per secret per month plus API call fees, which scales operational and licensing costs across large enterprises as documented by Belsoft Solutions. Rather than spending engineering capacity rotating static tokens, security organizations should shorten credential half-lives down to minutes or eliminate static secrets entirely using identity brokering.


How do static secrets differ from secretless, identity-based access?

Static secrets rely on shared, persistent strings such as API tokens, passwords, and private keys that authenticate whoever possesses them, whereas secretless, identity-based access verifies the cryptographic identity of the calling workload and mints short-lived permissions dynamically. The fundamental difference lies in trust: static secrets authenticate possession of a string, while identity-based systems authenticate the caller’s verified origin, workload context, and policy authorization.

According to the NHI Management Group framework, centralizing secrets into a vault preserves long-lived, high-risk credentials. Conversely, adopting an access layer built for non-human identities shifts workloads to just-in-time provisioning with native zero-trust boundaries.

Architectural Attribute Static Secrets and Traditional Vaults Secretless Identity-Based Access
Credential Lifespan Weeks, months, or indefinite Ephemeral (minutes or single execution)
Storage Overhead Vaults, config manifests, environment variables Zero stored secrets; nothing to leak
Authentication Basis Secret possession (bearer token) Workload identity, cryptographic proof
Operational Overhead Complex unsealing, replication, rotation scripts Frictionless integration, no rotation jobs
Auditability Logs vault access, but not downstream human intent Full runtime attribution from human to agent

Hush Security replaces static secrets, keys, and vaults by brokering non-human identity access at runtime. By shifting to identity-based, just-in-time access, organizations eliminate the risk of hardcoded credentials leaking across source control or continuous delivery runners while granting SecOps full visibility over non-human workflows.


How to manage credentials used by MCP servers safely?

Managing credentials used by Model Context Protocol (MCP) servers requires eliminating hardcoded API keys from configuration files and brokering access through a central runtime authorization layer. As engineering teams integrate artificial intelligence agents into developer tooling and delivery pipelines, developers frequently configure MCP servers using local configuration files that store plain-text access tokens for databases, Git providers, and internal microservices.

Real-world security research highlights the extent of this exposure. Hush Security’s State of MCP Configuration research analyzed 82,000 public config files, exposing how routinely developers inadvertently publish unencrypted API keys and authentication tokens in agent configurations. When an artificial intelligence agent inherits an employee’s personal access token or runs on a broad static key, any prompt injection or rogue agent task inherits those same excessive permissions.

To secure MCP servers effectively, platform engineering teams must apply four operational controls:

  • Isolate Agent Identities: Ensure every AI agent and connected MCP server runs under an independent, auditable machine identity rather than inheriting the engineer’s personal login.
  • Broker Runtime Permissions: Intercept agent requests using an authorization broker that issues short-lived, task-scoped access tokens rather than static credentials.
  • Enforce Policy Gates: Interpose approval controls on sensitive agent actions, allowing platform operators to permit, block, or require human-in-the-loop authorization before actions execute.
  • Establish Kill-Switch Controls: Maintain a centralized governance control plane capable of immediately revoking an agent’s runtime brokering session if anomalous behavior occurs.
                                    ┌───────────────────────┐
                                    │  MCP Server / Agent   │
                                    └──────────┬────────────┘
                                               │ (Runtime Request)
                                    ┌──────────▼────────────┐
                                    │ Hush Security Broker  │
                                    └──────────┬────────────┘
                                               │
                        ┌──────────────────────┴──────────────────────┐
                        ▼                                             ▼
           [Task-Scoped Approval Gate]                   [Block / Revoke Session]
                        │
                        ▼
          ┌───────────────────────────┐
          │ Target Database / SaaS API│
          └───────────────────────────┘

Adopting runtime brokering ensures that MCP servers never possess persistent machine secrets that could be extracted via prompt injection or configuration leaks.


What security controls prevent privilege escalation in CI/CD non-human identities?

Preventing privilege escalation in CI/CD non-human identities requires implementing strict pipeline-based access controls (PBAC), running unprivileged build workers, and establishing immutable audit trails. OWASP identifies both inadequate identity and access management (CICD-SEC-2) and insufficient flow control mechanisms (CICD-SEC-1) in its CI/CD Security Cheat Sheet as primary channels for privilege escalation within the continuous delivery lifecycle.

To prevent compromised build steps from expanding permissions across production clouds, engineering organizations must enforce five foundational safeguards:

  1. Pipeline-Based Access Controls (PBAC): Restrict the permissions granted to a workload identity based on the specific branch, repository, and workflow file executing the task. A pull request build from a fork must never receive permissions to request production cloud tokens.
  2. Ephemeral Runner Isolation: Execute all continuous integration jobs on single-use, isolated compute nodes or containers that terminate immediately upon build completion. This prevents malicious scripts from caching credentials on disk or snooping neighboring runner processes.
  3. Separation of Continuous Integration and Deployment: Maintain explicit boundaries between integration builds and deployment pushes. In accordance with NIST guidelines cited by OWASP, continuous delivery requires code to be manually verified or gate-checked before production releases, whereas continuous deployment automates release execution. Applying strict approval checks on automated production jobs prevents unauthorized deployments.
  4. Immutable SIEM Audit Shipping: Ensure every read, token exchange, and privileged action produces immutable audit logs shipped directly to an external SIEM platform. As emphasized in Ixiea’s 2026 secrets guidance, audit streams must be independent so that compromised pipeline workers or vaults cannot modify or erase their own access history.
  5. Runtime Policy Enforcement: Implement admission controllers and runtime policy enforcement to block pods or jobs attempting to run with root privileges or requesting unmapped cloud service accounts.

Common Secrets Management Mistakes to Avoid

When scaling sprawl reduction across enterprise platform teams, avoid these recurring operational traps:

  • Treating a Vault as a Sprawl Solution: Storing thousands of unmapped static credentials in HashiCorp Vault or cloud key vaults only centralizes secrets storage. Sprawl continues unless you actively eliminate static credentials in favor of workload identity federation.
  • Running Code Scanners Without Attribution: Generating lists of thousands of hardcoded secrets across legacy repositories without assigning named human owners results in unaddressed scanner alert fatigue.
  • Relying on Default Vendor Pipeline Configurations: As noted in the OWASP CI/CD Cheat Sheet, engineering organizations should never blindly rely on default vendor settings. SCM and automation servers like Jenkins must have debug endpoints disabled, least-privilege plugins configured, and unmasked environment logging prevented.
  • Permitting Long-Lived Personal Access Tokens in Pipelines: Allowing engineers to use personal access tokens (PATs) for service-to-service automation bypasses non-human identity governance and leaves persistent access active when employees depart.
  • Neglecting AI Agent and MCP Configurations: Overlooking the credentials embedded in developer MCP clients and artificial intelligence tooling leaves high-privilege static secrets entirely outside enterprise vault governance.

Platform teams ready to eliminate machine credential sprawl should begin by mapping runtime service accounts and exploring Hush Security’s platform to discover non-human identities and enforce secretless, just-in-time access across pipelines and AI agents.

Find Every AI Agent and NHI, Free
Get a Demo

Table of Contents

The advisory arrives midweek. It ends the way they all do: rotate all your secrets.

This week it came from several directions at once. A poisoned LiteLLM release ran a credential stealer every time Python started, in every environment it was installed in, whether or not anything used it. Separately, Railway told all its users to revoke and rotate every key. And OpenCode reported customer API keys stolen.

The pattern isn’t new. In March, an earlier LiteLLM compromise pulled CI secrets from roughly 2,500 organizations.

Different doors. The same instruction.

“Rotate everything” is the only instruction anyone can give

The advice is reasonable. Exposure is easy to assume: everything the process could read. So everything gets rotated. The hard part is doing it safely, when nobody knows who uses each secret.

The hunt begins: every copy of every key, in every vault, config file and pipeline. Every service that reads it. Then the change, everywhere at once. Miss one consumer, and revoking the old key takes it down.

Meanwhile, the clock is not yours. In this week’s LiteLLM incident, attackers were testing stolen cloud keys the same day. A careful rotation takes days.

Mapping who uses each secret is a hard problem of its own, and runtime visibility changes it. That was the subject of our last post. This post asks why there is a long-lived secret to steal at all.

Workload identity works only where the other side trusts it

The industry knows the better answer: workload identity. A service proves what it is, instead of presenting something it holds. The platform vouches for it, and it gets a token that expires in minutes. The major clouds have worked this way for years. Workload identity federation extends it beyond them: OpenAI, Anthropic, Snowflake and Databricks now accept those identities too. Where it is available, use it.

But most systems don’t accept it. A SaaS vendor, a database, a legacy internal API, a partner’s endpoint: few accept a federated token. There are hundreds of SaaS apps, and waiting for all of them is not a plan.

Your side can prove who it is. The other side still wants a secret.

So make every secret disposable

If those systems will keep asking for secrets, and some will be stolen, the goal changes: make a stolen one worth little, and recovering from it routine.

A better vault won’t get you there. It keeps a long-lived secret safer, but still long-lived. Applications fetch it and hold it, and copies spread until there are many sources of truth. Access rules per vault path are hard to keep tight, so a workload can usually reach secrets it never uses, and one compromised workload exposes all of them.

A disposable secret needs five properties:

  • Short-lived. It expires soon after it is issued, so an attacker’s window is short.
  • Scoped to need. It grants only what the workload actually uses, so a stolen copy reaches little.
  • One per workload. When one leaks, you know whose it was, and replacing it touches nothing else.
  • Owned by the system, not a person. Rotation happens because policy says so, not because someone remembered.
  • No code changes. Applications receive it the way they already read secrets.

Hush Access Manager

This is what we built Hush Access Manager to do.

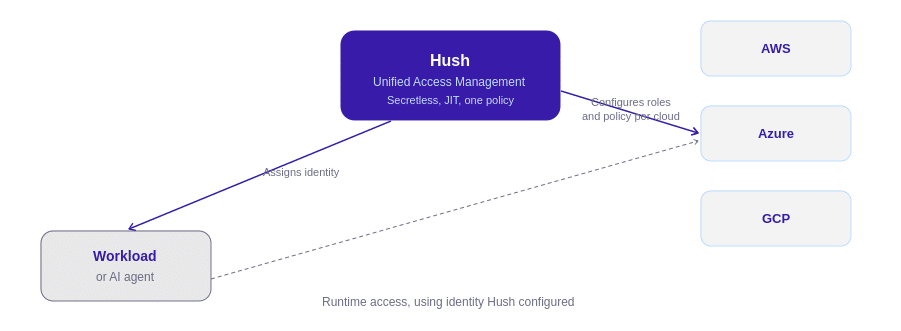
It bridges the two sides. On yours, access follows identity: a policy grants a workload access to a resource because of what it is, the way an IAM role does in the cloud. On the other side, the target still gets what it expects, a credential. But it is a disposable one, minted by Hush for that workload alone, scoped to its policy and short-lived. The workload never holds a long-lived secret, and nobody has to own one.

It works for the systems that never adopted workload identity: databases, SaaS, APIs and cross-cloud resources. Where a target does support federation, Hush provisions that instead.

Under the hood, it identifies workloads with SPIFFE, so you get workload identity without running SPIFFE yourself.

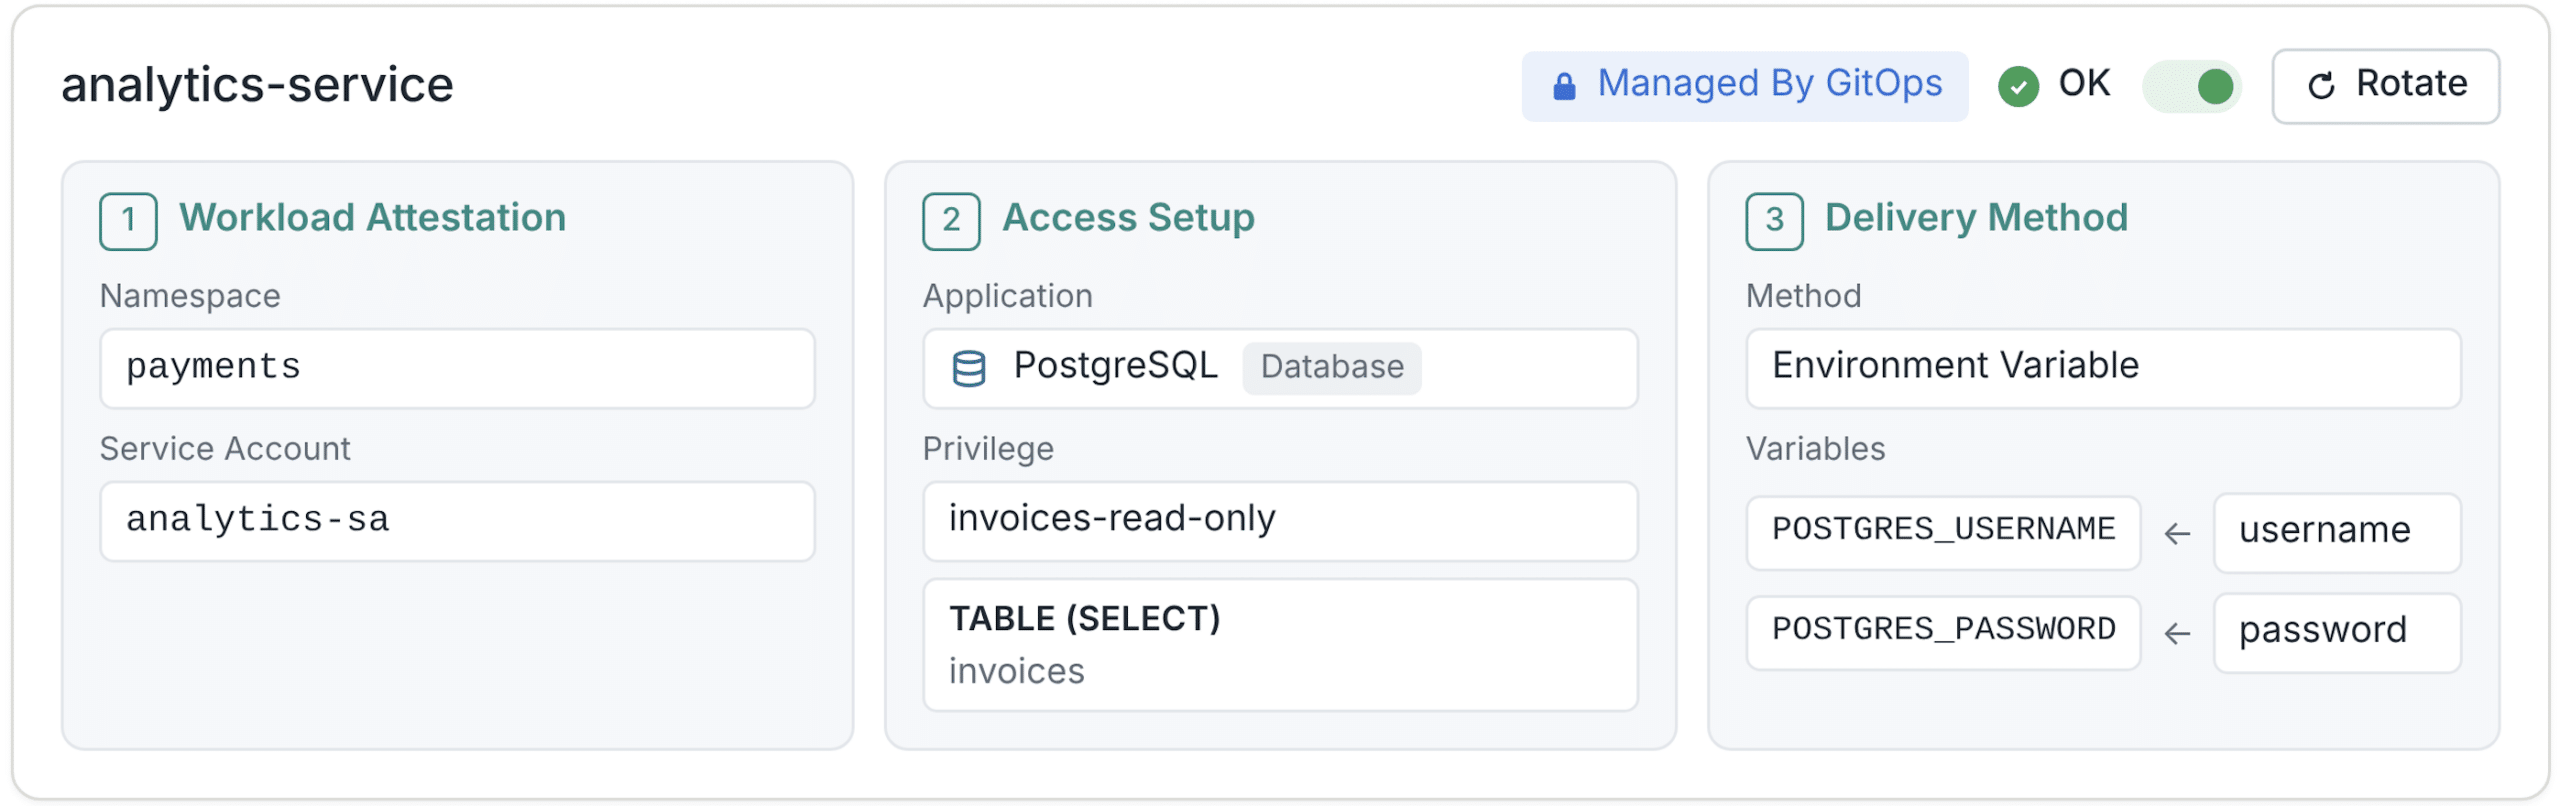
An example policy, simplified from the Hush console. It says who the workload is, what it may do, and how it receives its credentials. There is no secret in it. Rotate issues fresh credentials on demand.

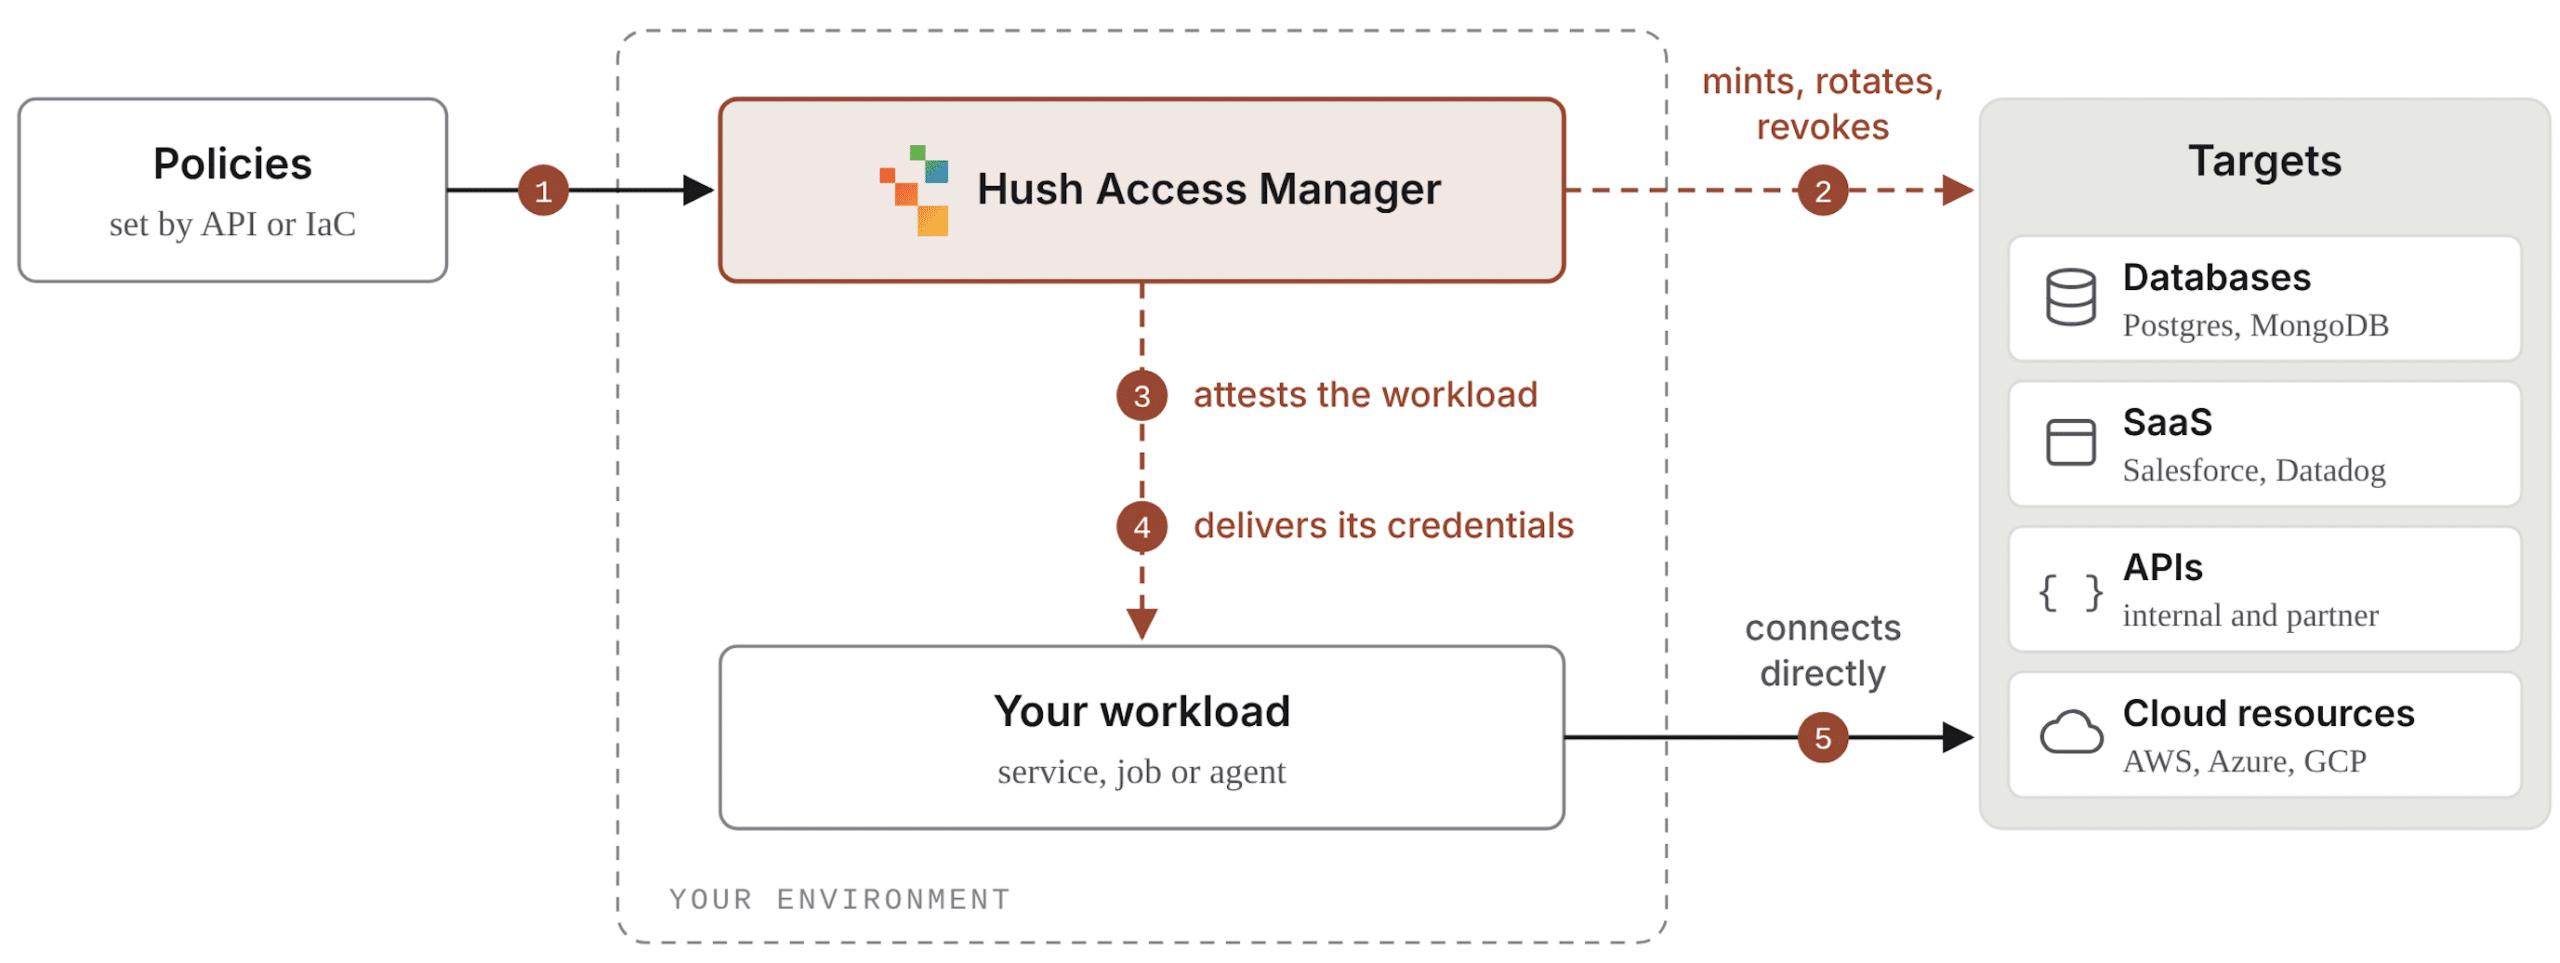
How it works

  • Define. You set policies by API or infrastructure as code: which workloads reach which resources, with what rights.
  • Mint. The Access Manager runs in your environment. It creates scoped credentials at each target, per policy, keeps rotating them, and revokes them when no workload matches anymore.
  • Attest. When a workload starts, the Access Manager verifies its identity and matches it to policy.
  • Deliver. Each workload receives only its own credentials, as environment variables or files. It needs no access to a vault, and no code changes.
  • Connect. The workload talks to the resource directly, in its native protocol. There is no proxy in the path.

The Access Manager runs in your environment. It manages credentials at each target and hands each workload only its own (dashed). The workload then talks to the target directly (solid): Hush is never in the path of your traffic. Numbers follow the steps above.

The same week, replayed

Run this week again with every credential managed this way.

The stealer still runs. It still finds credentials, in environment variables or files, wherever the workload keeps them.

Each credential it takes is short-lived, and belongs to one workload.

Once the bad package is gone, you redeploy the affected workloads. Hush hands them fresh credentials and retires the stolen copies. Every other workload keeps running untouched. Its credentials were never exposed, so there is nothing to rotate.

No hunt for copies. No spreadsheet of owners. No lost weekend.

Where to start

Start with the secret you would least like to see in a stolen archive. Pick one workload and one resource. Hush can suggest the first policy from what that workload already uses. Then let the Access Manager take it from there, and move on to the next one.

And ask the question this week raised: if you had to rotate everything tonight, how long would it take, and how sure would you be that you got it all?

How long would “tonight” take?
Connect one environment and see every secret, and every one you’d miss.
See your secret inventory for FREE

Find Every AI Agent and NHI, Free
Get a Demo

LiteLLM is Just the Latest Warning: The Access Model Built on Secrets Is Failing

Micha Rave's avatar
Micha Rave CEO and Co-Founder

Table of Contents

The latest LiteLLM breach should concern security leaders for reasons that go well beyond one compromised open-source project. It’s another entry in a growing list of attacks following an increasingly familiar pattern: attackers gain an initial foothold, obtain credentials, and use those secrets to expand their reach.

We’ve seen this before. We’re seeing it more frequently. And the time between initial compromise and potential damage is shrinking.

In March, LiteLLM was compromised as part of a broader software supply chain campaign that also affected projects including Trivy, Checkmarx, and Telnyx. Seven months later, on October 21, attackers compromised LiteLLM’s release pipeline again, distributing malicious software through its official channels.

Different attacks, same recurring weakness: credentials that can be stolen and reused to turn one compromised system into access to many others.

The real damage begins after the first breach

The October LiteLLM incident shows the problem clearly.

According to LiteLLM’s preliminary investigation, attackers appear to have accessed an exposed internal deployment and obtained GitHub authentication tokens from its logs. Those credentials allowed them to manipulate the release pipeline and distribute a poisoned version of the software.

The malicious release was designed to harvest additional credentials, including cloud access keys, SSH keys, AI provider secrets, and credentials stored in LiteLLM’s own proxy database.

An attacker obtains credentials from one system, uses them to compromise a trusted distribution channel, and turns that channel into a mechanism for collecting credentials from potentially many more systems.

Each successful compromise creates opportunities for the next.

The pace is accelerating

The threat landscape is changing in two ways: attackers have more potential entry points, and the tools available to exploit them are becoming far more capable.

Palo Alto Networks’ 2026 Unit 42 Incident Response Report found that identity weaknesses played a material role in nearly 90% of its investigations. It also reported that the fastest attacks in 2025 exfiltrated data at four times the previous speed.

Meanwhile, advances in AI are making sophisticated offensive capabilities more accessible. Anthropic has demonstrated that its Claude Mythos Preview model can identify and exploit previously unknown vulnerabilities across major operating systems and browsers.

As vulnerability discovery and exploitation become increasingly automated, organizations should expect less time to identify and contain an intrusion.

Preventing breaches still matters. Organizations must continue securing their software supply chains, patching vulnerabilities, and strengthening authentication.

But prevention alone is no longer a sufficient strategy.

Security leaders also need to ask a different question: When an attacker gets in, how much access can they gain, and how quickly can they expand it?

The problem is the access model

For decades, machine-to-machine access has depended heavily on secrets. API keys, service account passwords, tokens, and other credentials are embedded in applications, stored in configuration files, passed through pipelines, and sometimes exposed in logs.

That model was already difficult to secure in traditional infrastructure. Now, organizations are adding thousands of workloads, integrations, and autonomous AI agents that need access to enterprise resources.

Every additional long-lived credential creates another opportunity for theft and reuse. Every overly permissive identity increases the potential blast radius.

Since the news broke, I’ve had calls with security leaders cut short because their teams were busy dealing with the fallout. If your team is one of them, I know how hard it’s been.

Rotating compromised credentials is the right immediate response. But anyone who has done it at scale knows the pain: tracking down every key that might be exposed, pulling engineers off their work, and making sure nothing breaks along the way. And when it’s over, the underlying model is still intact. New secrets replace the old ones, in the same places, with the same exposure.

We need to reduce our dependence on reusable secrets and move toward an access model built around identity, with access continuously governed according to what each workload or agent is authorized to do.

That means:

  • Verified, accountable identities: Every workload and AI agent has a distinct identity, rather than relying on shared, persistent credentials.
  • Just-in-time access: Permissions and credentials are scoped to specific tasks and limited in duration, reducing their value if compromised.
  • Least Agency: AI agents receive only the capabilities their tasks require, with sensitive actions subject to appropriate controls.
  • Continuous runtime visibility: Organizations can see which identities access which resources, detect unusual activity, and enforce policy as access happens.

These controls cannot make a software supply chain compromise impossible. They can, however, make stolen credentials far less useful and substantially limit what an attacker can reach after gaining access.

The next breach is a matter of when

LiteLLM won’t be the last incident of this kind. Another compromised dependency, exposed token, or hijacked release pipeline will make headlines.

The immediate response will again involve investigation, patching, and credential rotation. All of those steps are necessary.

But the more important question is whether organizations will still be exposing the same reusable credentials, granting the same standing privileges, and allowing attackers the same opportunities to move from one system to the next.

As attacks become faster and more frequent, containing their impact becomes just as important as preventing the initial intrusion.

At Hush, this is the future we’re building toward: an identity-based access model for workloads and AI agents, where access is verified, scoped, and governed at runtime without relying on long-lived secrets.

The next breach may be inevitable. The chain of access after it is not.

Find Every AI Agent and NHI, Free
Get a Demo

AI Agents Don’t Have a Behavior Problem. They Have an Identity Problem.

Micha Rave's avatar
Micha Rave CEO and Co-Founder

Table of Contents

Personal AI agents just went mainstream

In a single month, the personal AI agent went mainstream. Meta’s Muse, launched on September 8, hit the top of Apple’s free app chart within 10 days. Instinct, a startup you text or call, just raised $1 billion at a $10 billion valuation.

These aren’t chatbots. They read your email, book, buy and correspond on your behalf. To do that, Instinct users give the agent broad authority to read and store data from any account they connect, and to make purchases and accept agreements in their name.

That’s the consumer version. The enterprise version is already running inside your organization: agents opening tickets, pushing code, pulling customer data and approving workflows. Same pattern, higher stakes. Once an agent acts, it needs access. And access is what attackers are looking for.

Behavior is only half the problem

Most of the security conversation is about agent behavior: guardrails, prompt injection, what the model is allowed to say. That’s real, but it’s half the problem.

Every agent authenticates to something: a database, an API, a SaaS app, another agent. That authentication is a non-human identity (NHI). A key, a token, a service account. Ship an agent, and you’ve also shipped an identity, usually one nobody registered and nobody owns. If that credential leaks, the guardrails don’t matter.

In research we published this month, we analyzed roughly 82,000 public MCP configuration files, the layer that connects agents to enterprise systems. We found secrets and access keys embedded in plain sight, available to grab and exploit. This isn’t a model problem. It’s an identity problem.

Three common questions leave organizations exposed. Here’s what to ask instead.

1. Don’t ask how many agents you have. Ask what identities they run on, who owns them, and how fast you can shut them down.

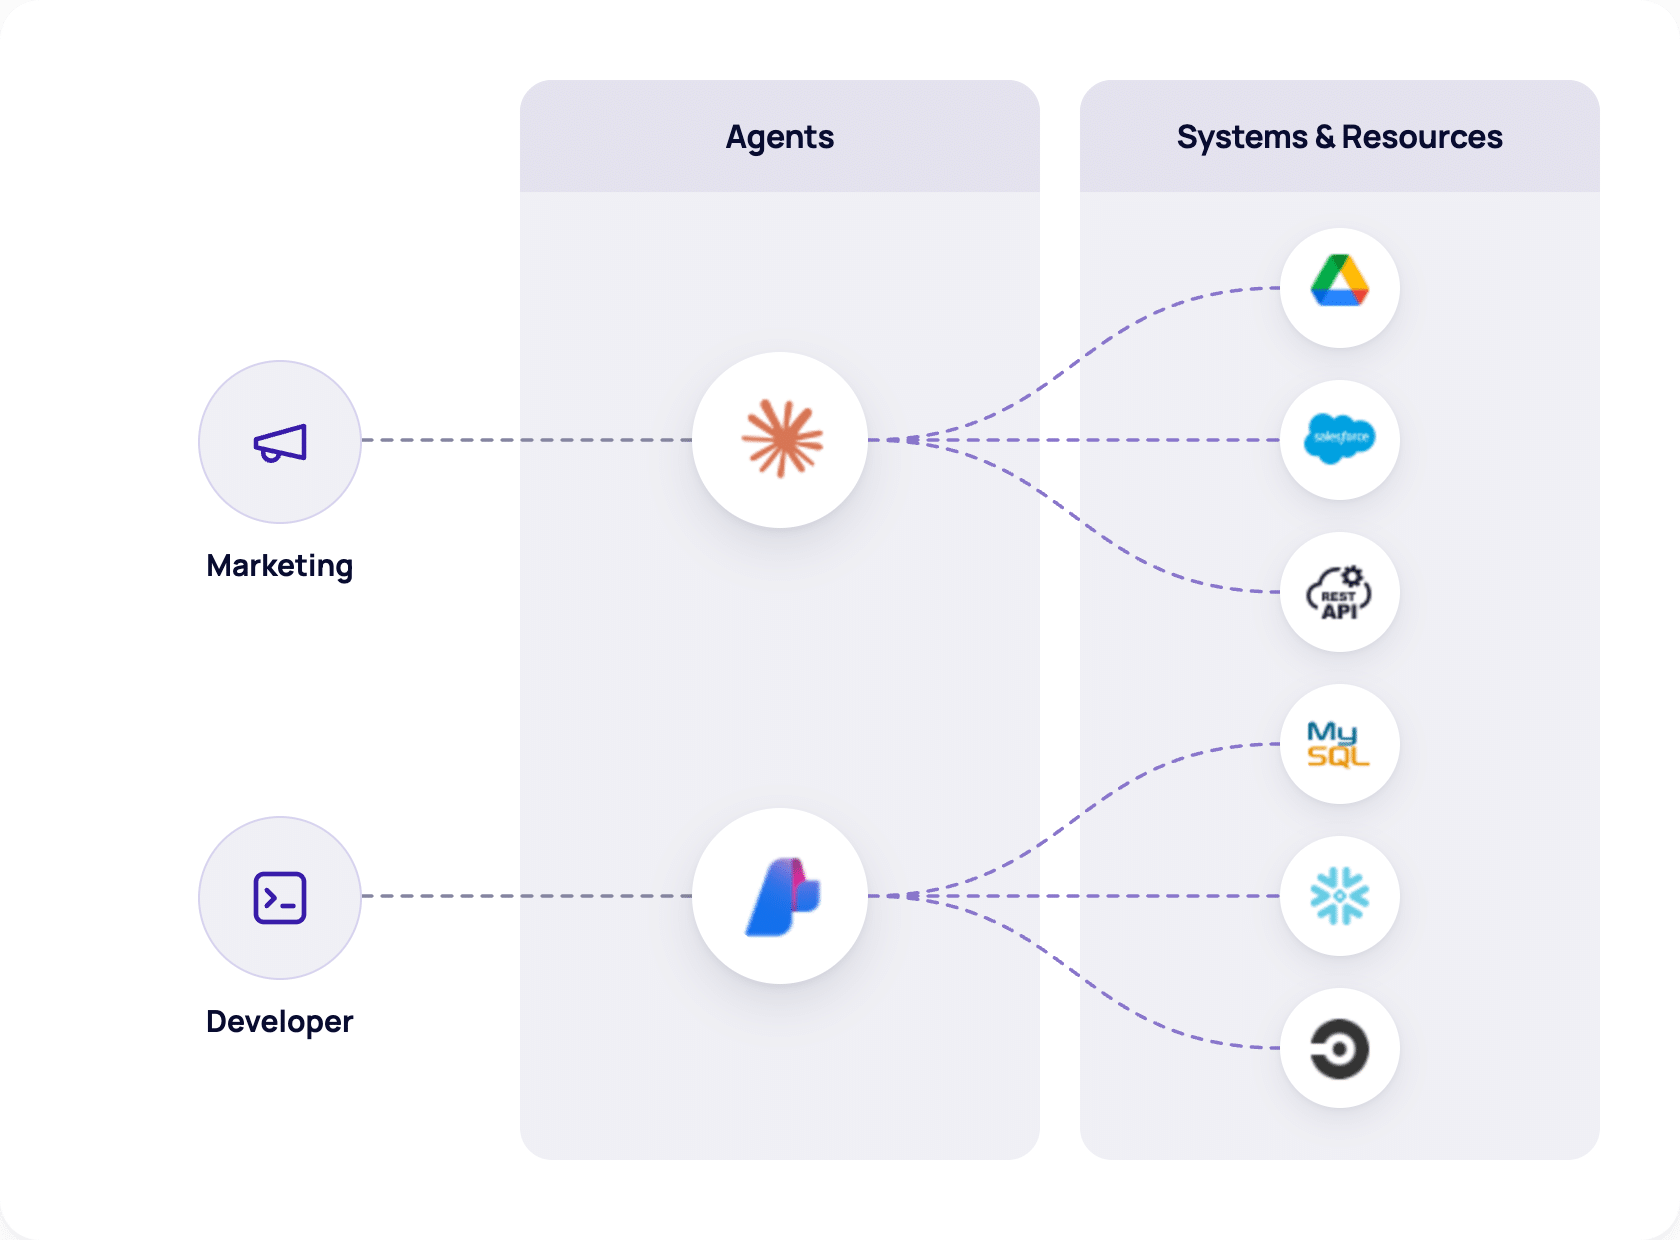
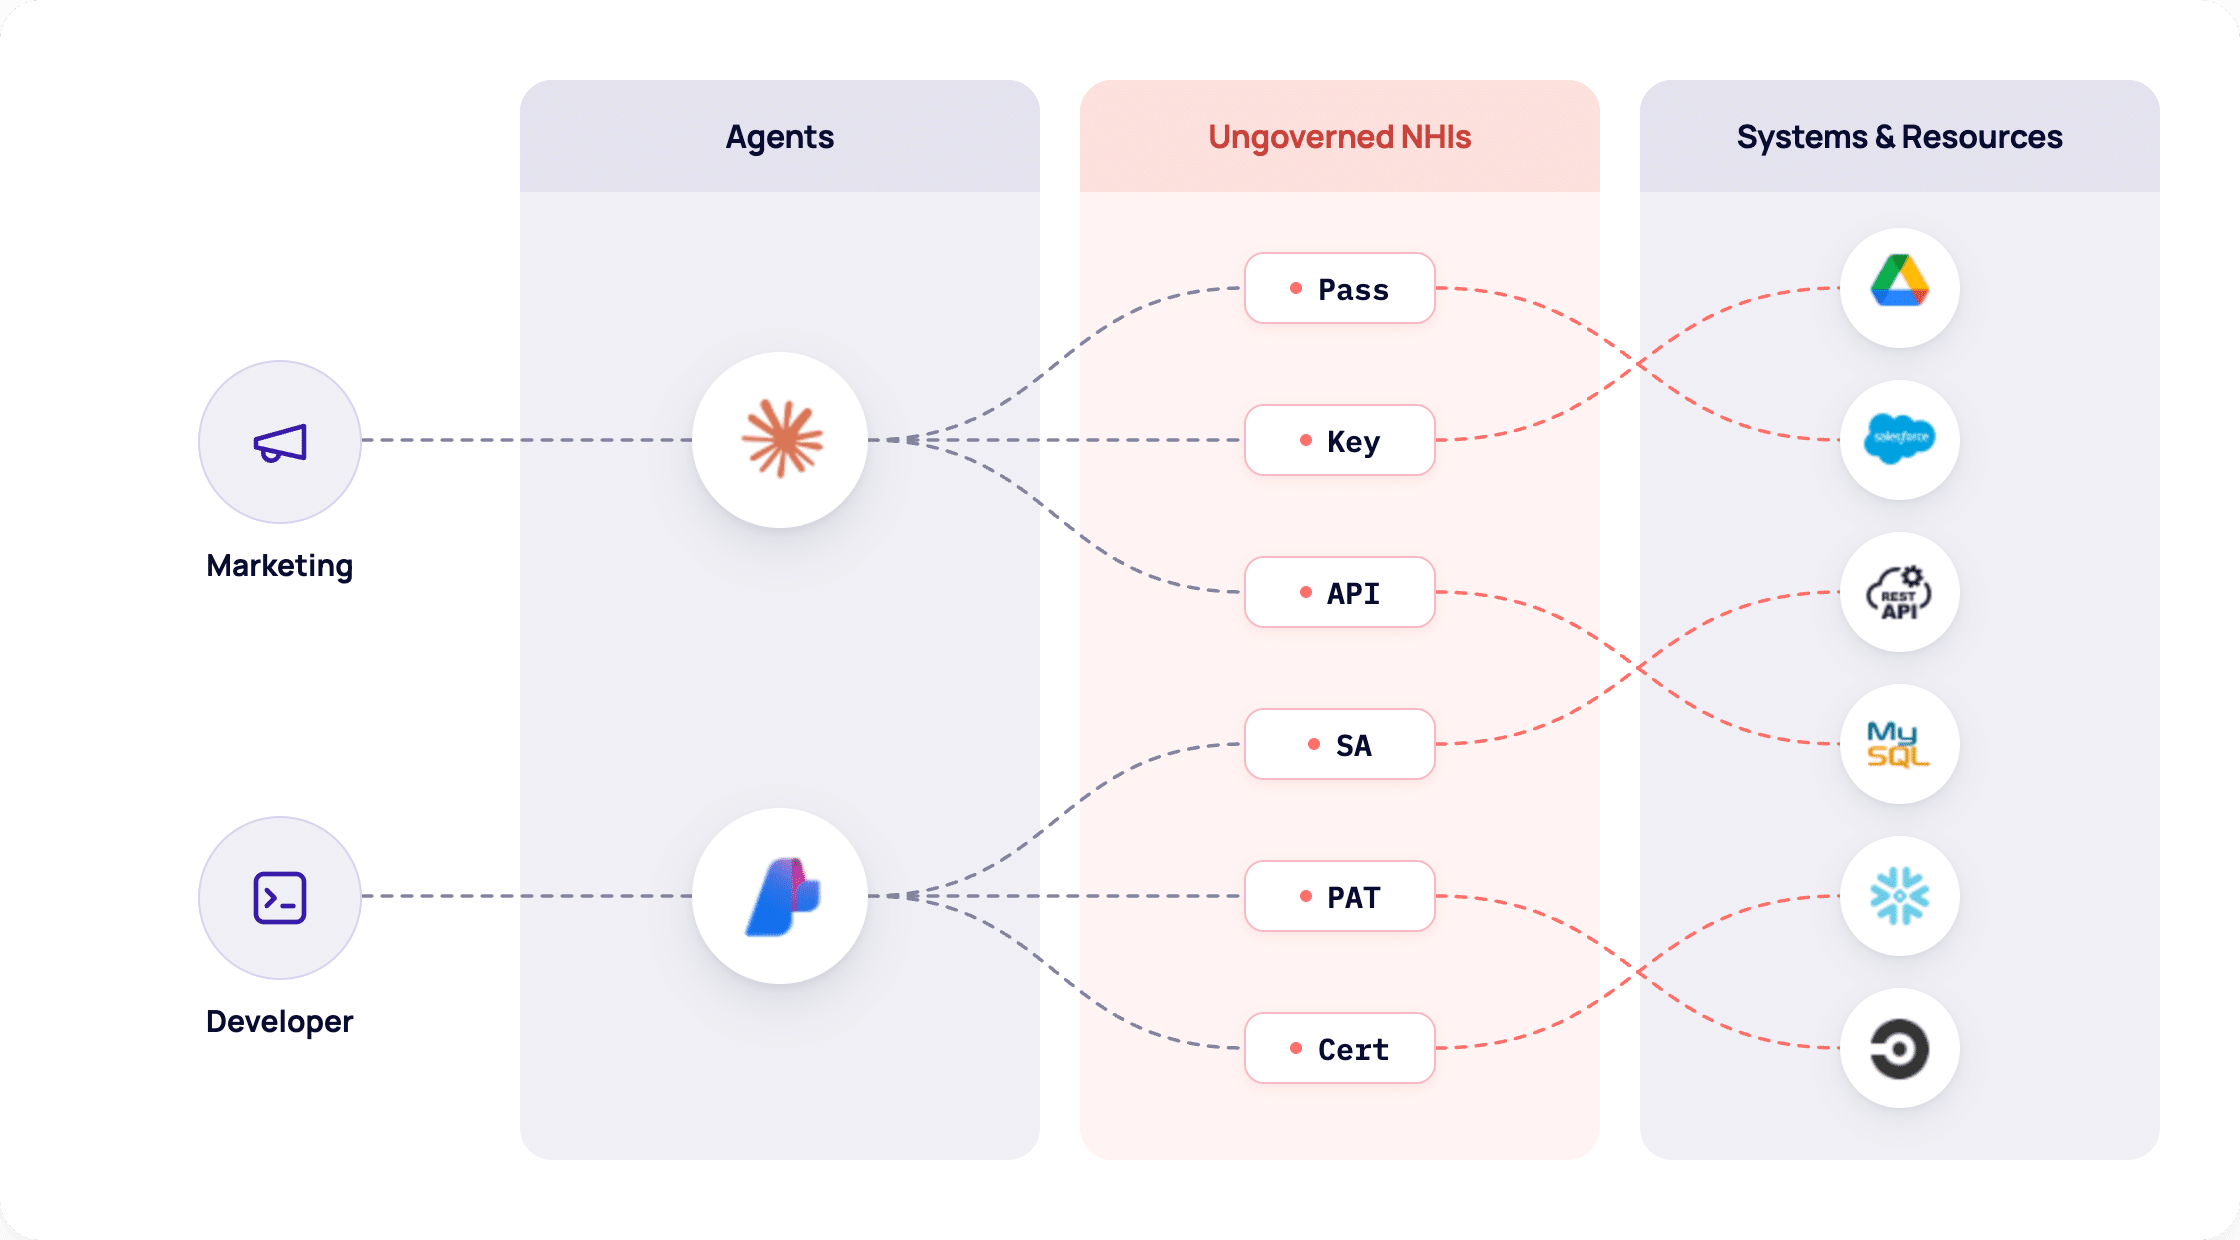
Picture two teams. A developer connects a coding agent to MySQL, Snowflake and CI. Marketing connects an agent to Drive, Salesforce and a REST API. Two agents, both approved. This is the picture most security teams have.

But to make them work, someone minted a password, a key, an API token, a service account, a personal access token and a certificate. Two agents. Six identities nobody inventoried. They weren’t provisioned as identities. They were created as a side effect of getting something to work, fast.

That’s why counting agents gives you the wrong number. The agents aren’t what touched your systems. Their credentials are. Every one of those identities needs a named owner, a place in a central inventory, and a risk profile: which systems it reaches, what data it can touch, and what happens if it’s compromised. An agent with read access to a wiki and an agent that can move money are not the same problem.

And every agent needs a kill switch. When one misbehaves or its credentials leak, the response can’t be a hunt for scattered keys across repos and config files. When each agent has a single verified identity, revoking it cuts off all access instantly, everywhere, in one action. If you can’t stop an agent in seconds, you don’t control it.

2. Don’t ask if the agent is secure. Ask what it’s allowed to do, and who decided.

The fastest way to connect an agent is to hand it a static key with broad permissions. That key usually carries whatever scope its creator had that day, serves every user the same way, and outlives the project, sometimes the employee. It works until it leaks. Then the attacker gets everything the agent can do, and often more.

The answer isn’t better secret rotation. It’s removing standing secrets altogether. Agents should authenticate as identities, not with shared keys, and receive least agency: only what the task requires, scoped to the user or team they act for, expiring when the task ends.

If an employee can’t delete a database, neither can their agent. That policy already lives in your identity provider. It just needs to extend to agents. Nothing to rotate, because nothing persists.

3. Don’t ask what happened after the incident. Ask what was stopped in the moment.

Plenty of tools produce polished risk dashboards and send alerts. That matters, but agents operate at machine speed. By the time the alert lands, the data is gone. And when you investigate, the log says “API key.” It doesn’t say which agent, which user, or which task.

The difference is between monitoring and enforcement. Real control sits in the path of the action itself: every agent request tied to an identity, checked against policy, allowed or blocked in real time, and recorded with full attribution. That delivers both protection and the ability to show regulators and the board exactly who did what, when and why.

Your new workforce needs identity-first security

What ties these questions together is a shift in how we think about enterprise identity. Your people get an identity, an owner, a lifecycle and offboarding. Your agents get a secret in a vault, or an env file, and a hope that someone remembers it exists.

AI agents are a new workforce: they operate like machines, decide like people, and multiply faster than both. They need to be managed like one.

Leadership doesn’t have to choose between speed and security. It needs to ask different questions: not how many agents, but what identities they run on; not whether they’re secure, but what they’re allowed to do; not what happened, but what was stopped.

Organizations that secure both the agent and the identity it runs on will scale AI with confidence. The rest will discover their shadow identities the hard way.

Find Every AI Agent and NHI, Free
Get a Demo

Why Cross-Cloud Federation for Workload Access Is So Hard

Micha Rave's avatar
Micha Rave CEO and Co-Founder

Table of Contents

Most workloads no longer live in one cloud. A service runs in AWS, calls a database in GCP, and pulls a secret from an Azure vault. Each of those hops needs access. And access means identity.

For humans, we solved this. Single sign-on, one IdP, federated trust. For workloads and AI agents, the tools now exist too, but using them across clouds is hard enough that most teams still fall back on long-lived secrets. Cross-cloud workload access is still stitched together by hand, and it breaks in predictable ways.

Here is why it is hard.

Every cloud is its own trust island

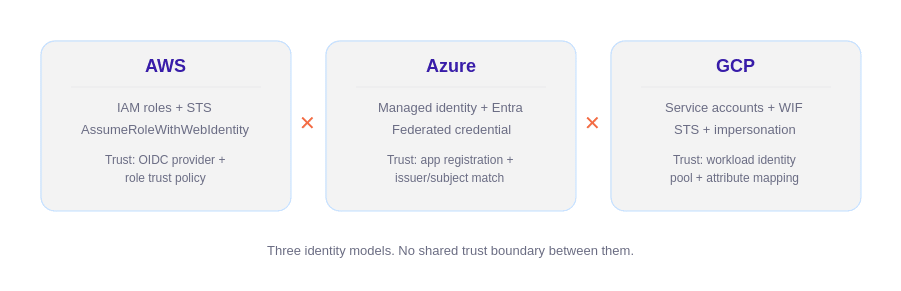
AWS has IAM roles and STS. GCP has service accounts. Azure has managed identities and Entra. Each was built to establish trust inside its own boundary. None was built to trust the others.

So the moment a workload needs to reach across clouds, there is no shared notion of who it is. The identity that AWS understands is meaningless to GCP.

Tokens do not translate

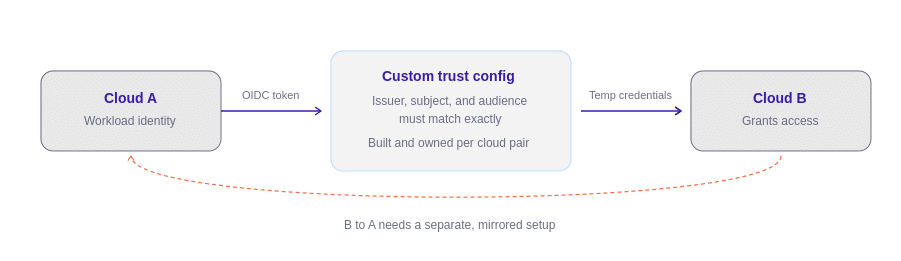
Federation on paper means exchanging trust through OIDC or SAML. In practice, token formats and claim semantics differ across providers. An identity assertion that satisfies one cloud’s authorizer maps poorly, or not at all, onto another’s policy engine.

You end up writing custom claim mapping for every pair. It is brittle, and it drifts.

What it actually takes to federate

Take a concrete case: Kubernetes pods that need to reach all three major clouds. Pods run in EKS, AKS, or GKE, and each has to authenticate to the other two providers. That alone is a three by three matrix, and every off-diagonal cell is its own build.

Each cloud speaks a different dialect:

  • AWS. An OIDC provider plus a role trust policy pinning subject and audience, assumed via AssumeRoleWithWebIdentity — that covers inbound trust. Outbound just got easier too: the new IAM Outbound Identity Federation issues a short-lived JWT via GetWebIdentityToken, no stored key needed.
  • Azure. An app registration with a federated identity credential mapping issuer and subject, plus RBAC roles.
  • GCP. A workload identity pool with attribute mappings, feeding a two-hop exchange: STS, then service account impersonation.

Same goal, three mental models, and the details bite: a separate token per target cloud, each with its own audience; claim matching that has to be exact; token lifetimes that disagree across clouds; and failures that surface as a bare 403 with no real signal.

None of this ships out of the box. AWS’s outbound federation closes its half of the gap, but the other five directions in the matrix, and every receiving side, still have to be built by hand.

And then you maintain it forever

Building it once is not the real cost. Keeping it alive is.

  • Teardown mirrors setup. Roles, providers, pools, and credentials all need undoing, across all three clouds. Cleanup takes as long as the build.
  • Recreate a cluster and trust breaks. The OIDC issuer changes, and every federated credential pointing at the old one has to be re-registered.
  • Config drifts in three dialects. Trust lives in separate IaC per cloud, and drift stays invisible until access silently breaks.
  • Hardening never ends. Tighter subject matching, scoped roles, dedicated pools per cluster: every improvement is more config to own.

Multiply that across every workload, cluster, and cloud pair, and cross-cloud identity quietly becomes a full-time job for a platform or security team.

Workloads are ephemeral

Containers scale up and down. Functions spin up for milliseconds. Autoscaling groups churn constantly. Static, long-lived credentials do not fit this world, but that is exactly what most cross-cloud setups fall back on.

The identity has to be issued at runtime, scoped to the moment, and gone when the work is done. Very few federation schemes do this cleanly across boundaries.

Secrets creep back in

When federation gets too painful, teams take the shortcut. They drop a long-lived key or a service account JSON into an environment variable and move on. Now you have a static secret crossing cloud boundaries, and it is the single most common root cause of breach.

The hard path gets abandoned, and the insecure path wins by default. Even where native federation now exists, migrating an existing estate is a project, not a switch: hundreds of integrations, each with its own owner, deadline, and risk tolerance. Under pressure, teams keep the old long-lived key running as a fallback, or never get around to retiring it, and the legacy secret quietly persists alongside the new setup.

No unified audit, no unified policy

Even when access works, visibility does not. Each cloud logs its own events in its own format. There is no single answer to “which workload accessed what, in which cloud, and why.” Policy is just as fragmented. Every provider speaks a different IAM dialect, so intent has to be re-expressed everywhere and stays consistent nowhere.

At the scale of modern NHIs and AI agents, which dwarf the number of humans, none of this can be managed by hand.

How Hush solves this

Hush puts one identity-based access layer across every cloud. Workloads and agents get a single identity, not a pile of per-cloud credentials.

  • One trust plane, not n by n. Hush brokers access across clouds through standards-based token exchange, so you stop hand-building trust between every pair.
  • JIT by default, no static secrets. Access is issued at runtime, scoped, and short-lived. Nothing long-lived crosses a boundary.
  • One inventory, one audit trail. Every agent and workload is accounted for, and every access is logged in one place, across every cloud.
  • Policy, not keys. Express intent once. Enforce it everywhere.

Cross-cloud federation is hard because the clouds were never built to trust each other. Hush gives them a common layer that was.

Let’s look deeper into how it’s done.

Hush, cloud federation done right

Hush becomes the one issuer every cloud trusts, instead of every cloud having to trust every other cloud. You register Hush’s OIDC issuer with AWS, Azure, and GCP once each, using the same federation primitives as before:

  • an IAM OIDC provider and trust policy in AWS
  • a federated identity credential in Azure
  • a workload identity pool in GCP

Three registrations instead of six.

That registration happens once, from the Hush console. Adding a connector for a given cloud walks through the application type and then surfaces the exact OIDC parameters, issuer URL and audience, to paste into that cloud’s identity provider setup:

From there, Hush signs a short-lived token for the workload’s identity and mounts it directly into the pod. The workload presents that token to whichever cloud it needs, and gets back a native, temporary credential from that cloud’s own STS. Hush never sees or holds the downstream credential, it only vouches for the workload that’s asking.

Hush also owns the token’s lifecycle end to end. It rotates the signed token before it expires, and refreshes it again if the workload outlives the cloud’s own credential 

lifetime, AWS session tokens cap at 12 hours, for instance. A long-running workload never has to detect an expiring credential or handle renewal itself.

The result: one identity, one trust relationship to configure per cloud instead of per pair, and access that is short-lived by construction rather than something a team has to remember to rotate.

Cross-cloud federation is hard because the clouds were never built to trust each other. Hush gives them a common layer that was.

Find Every AI Agent and NHI, Free
Get a Demo

Agentic AI Just Got an Enterprise Access Layer

Shmulik Ladkani's avatar
Shmulik Ladkani CTO and Co-Founder

Table of Contents

Anthropic recently shipped the Enterprise-Managed Authorization (EMA) extension for Claude’s MCP connectors, which lets IT admins configure tools such as Asana, Figma, and Linear once through their existing identity provider. Authorized employee end users can then inherit access at login without needing any additional individual OAuth approvals.

Under the hood, Anthropic’s EMA relies on a specific IETF draft spec called ID-JAG.

It’s worthwhile to take a deep dive into how it actually works, what makes it such an elegantly well-designed piece of plumbing, and to map out what it solves for and what gaps might still need to be solved for by its users.

The Problem ID-JAG Solves

An agent acting on your behalf touches a lot of apps in one task: the wiki, Slack, a Jira ticket, your calendar. Each is a separate vendor, usually reached through something like MCP.

Each of those apps needs to know who you are and what you’ve allowed the agent to do before handing over any data. The standard way to establish that is OAuth, which normally means a human in the loop: a redirect, a login screen, and an “Allow Access” click, once per app.

That works fine when a human is connecting one app, once. It doesn’t work when an agent needs ten services in the course of a single task and there’s nobody around to click “Allow” each time a new tool gets invoked. The actual complaint isn’t “too much security”; it’s that you already authenticated once, this morning, to SSO, and every downstream tool is making you prove it again.

Enter ID-JAG

ID-JAG, or Identity Assertion JWT Authorization Grant, is an IETF draft built to answer exactly that complaint, for one specific, well-bounded case: the apps involved already trust the same identity provider for login.

Instead of the agent asking you for permission app by app, it goes back to the IdP that handled this morning’s login and asks it to vouch for it. The IdP issues a short-lived token: this agent is acting for this user, and here’s what it should be allowed to do. The receiving app still decides whether to trust that and what to actually grant. The IdP is making an introduction, not issuing a blank check.

In practice:

You sign in to the agent via company SSO, as usual.

When the agent needs a new app, it goes to the IdP, not to you, and requests a token scoped to that app.

The agent hands that token to the app, which exchanges it for a normal access token under its own rules.

The agent calls the app’s API with that access token.

No second login, no per-app click. You authenticated once; everything downstream gets brokered through trust that already existed.

The Architectural Elegance of ID-JAG

ID-JAG doesn’t invent new cryptography or a new trust model. It combines two existing OAuth pieces, Token Exchange and the JWT Bearer grant, and defines exactly what goes inside the token: who’s vouching for the user, who’s acting on their behalf, what they’re allowed to do, and which app it’s for.

That specificity is what makes it useful. With those claims pinned down, an identity provider from one vendor and an app from another can implement the flow independently and still understand each other.

It’s also not really an “AI agent spec,” even though agents are why everyone’s suddenly paying attention. The worked example in the draft itself has nothing to do with agents: a company wiki embedding a live preview from a chat app, scoped to the viewing employee, with no consent prompt. Same mechanism, much older problem.

The boundary is also part of the design. ID-JAG only works between apps that already share an IdP for SSO. In most B2B and enterprise environments, that is already the norm. By staying inside that existing trust fabric, ID-JAG avoids turning agent authorization into a new identity system.

Why ID-JAG Is Necessary but Not Complete

ID-JAG decides whether an agent should be allowed to talk to a given app at all, and it does that job well, without making anyone click “Allow” repeatedly. That decision happens once, at grant time. It has no visibility into what the agent does five minutes later when it actually picks up a tool and uses it.

If a connected agent gets manipulated into taking an action it shouldn’t, ID-JAG isn’t the layer that catches it; that’s a different question than “can this agent reach this app.” You still need something that governs actions: per-action permissions instead of one broad standing scope, human-in-the-loop approval for anything sensitive enough to warrant it, centralized action-level audit, and credentials the agent itself never directly holds.

These two layers aren’t competing; they reinforce each other. Action-level governance needs to know who’s acting in order to apply per-user policy and produce a real audit trail, and a clean per-user grant is exactly what ID-JAG gives you, in place of the shared service accounts and static API keys that agents have mostly been running behind until now.

The Takeaway

ID-JAG is good infrastructure: two existing OAuth pieces, recombined precisely, removing the biggest piece of friction in connecting agents to apps inside an enterprise’s existing trust fabric, without inventing new trust assumptions. It’s already shipping, including Claude, VS Code, and a growing list of MCP servers, which tells you the industry agrees. Adopt it for the connection layer, and pair it with something that governs actions. Together, that’s the full picture.

Find Every AI Agent and NHI, Free
Get a Demo

Table of Contents

Claude Tag (their new Slack-native agent) introduces a different authorization model. Instead of the agent acting as the user who invoked it, the agent gets its own identity — scoped per channel, with its own credentials and permissions.

What changes:

  • Old model: “What can this user do?” → agent inherits the requester’s permissions.
  • New model: “What can this agent do in this channel?” → permissions attach to the agent, not the human.

The engineering is solid, and the innovation is amazing. But security and risk seems a bit neglected.

The problems:

  1. Confused deputy. Any channel member can invoke the agent. So a user with no access to a repo can ask the agent to read it, if the channel grants the agent that access. The human’s own permissions are never checked — privilege escalation by design.
  2. Long-lived NHI sprawl. Every channel gets its own scoped identity. That’s a fleet of long-lived, broadly-scoped credentials multiplying by design — the exact problem the industry has spent years failing to contain with human service accounts, now reborn for agents and scaling faster.
  3. Audit gaps. Actions land under a shared service account. In ambient mode across many channels, you lose attribution — you can see that the agent acted, not which human triggered it or why. The log captures identity and config lifecycle, not the substance of what was done.
  4. Missing guardrails. Access is granted at the channel level, not the action level. There’s no least-agency enforcement — once the agent holds a credential, nothing constrains which actions it takes with it. Anthropic’s own advice is “grant generous access from the start.”

What should’ve been done:

  • Effective permissions = agent scope ∩ requesting user’s scope. The agent should never do what the human couldn’t.
  • Action-level least-agency, not channel-level grants.
  • Audit that ties every agent action back to a responsible human.
  • Open the auth layer to an emerging standard like ID-JAG, Identity Assertion JWT Authorization Grant. instead of a proprietary, single-vendor model. It lets the enterprise IdP broker cross-domain access — so agent identity travels across IdPs and tools under central control, not just inside Anthropic’s walls.

Credit where due: Anthropic’s own “What’s next” addresses two of these directly — just-in-time credential grants (approve a single sensitive action in the moment without permanently widening scope) and an identity-aware overlay that adds user-level checks, so Claude only acts when both the channel’s profile and the requesting user’s permissions allow it. That’s the agent ∩ user model, and it’s the right direction. The gap is that it’s roadmap, not shipped — and the access model went live with “grant generously” as the default in the meantime.

Find Every AI Agent and NHI, Free
Get a Demo

The Anthropic Zero Trust Guide Is Excellent. Here Is What You Need to Implement It.

Micha Rave's avatar
Micha Rave CEO and Co-Founder

Table of Contents

Zero Trust for AI agents is the right framework for this moment. Anthropic published their guide on it this month, and the thing I keep coming back to is how many of its controls rest on a single assumption: that you already have cryptographic, runtime identity for your agents and non-human workloads. Most organizations do not. That is the gap this post is about, and it is the gap Hush was built to close.

I want to say upfront that the guide is one of the best pieces of practical security writing I have seen on this topic. It is specific, grounded in real threats, and gives architects and engineers something actionable. If you build or secure AI-driven systems, read it. This post is my practitioner’s walkthrough, with a direct lens on where Hush fits into the implementation.

Why AI Agent Security Requires a New Zero Trust Approach

Most security frameworks describe what good looks like in theory. This one is grounded in what attacks already look like in practice. The opening observation alone is worth sitting with: frontier AI models are compressing the window between vulnerability and exploit from months to hours.

The framework introduces a design test worth applying to every control you currently have in place: does this make the attack impossible, or just tedious? Controls that work through friction, such as rate limits and non-standard ports, degrade significantly against an attacker operating at machine speed. I think that framing is exactly right.

Autonomous AI systems change the attack surface in ways traditional security models do not account for. Agents interpret natural language, invoke tools and MCP servers, maintain memory across sessions, and coordinate with other agents. A compromised MCP descriptor can silently redirect tool calls. A poisoned memory entry corrupts every session that follows. These are not hypothetical threats. The first malicious MCP server impersonating a legitimate email service, silently copying all outbound messages, was documented in the wild. The guide maps all of this carefully, and regulated industries in particular should pay attention: the framework aligns directly with HIPAA, FINRA, GDPR, and FedRAMP requirements that are already in force.

The Framework’s Design Test

When evaluating any control, ask: does this make the attack impossible, or just tedious? Controls whose value comes from friction degrade significantly against an adversary that can grind through tedious steps at scale.

Non-Human Identity Is the Foundation Zero Trust for AI Agents Requires

The guide structures recommendations across three tiers: Foundation, Enterprise, and Advanced.

Foundation requires unique cryptographic identifiers for every agent instance, appearing in all logs and access requests.

Enterprise adds certificate-based authentication with lifecycle management.

Advanced moves to hardware-backed identity with attestation.

These tiers give teams a clear progression. Worth calling out directly: static API keys and embedded credentials are among the first things an attacker with model-assisted code analysis will find. The prescription is short-lived tokens issued by an identity provider, measured in minutes rather than days. That is exactly the model Hush is built around.

Hush issues credentials at the moment a workload needs access, scoped to the exact task, and expires them immediately after use. No long-lived secrets to rotate, audit, or accidentally expose. The SPIFFE framework underpins all of it, giving every workload and agent a verifiable runtime identity.

On the Framework’s Credential Guidance

Short-lived, narrowly-scoped tokens issued by an identity provider are the new baseline. Rotating a credential that can be found in a lockfile does not meaningfully raise the cost to an AI-assisted attacker.

Agent Identity Verification: How Hush Maps to Each Zero Trust Tier

The table below maps each identity and authentication requirement from the guide to the corresponding Hush capability.

Tier Framework Requirement Hush Capability
Foundation Unique cryptographic identifiers per agent instance; IDs appear in all logs and access requests. Runtime discovery assigns persistent, cryptographically rooted identity to every workload, agent, and NHI. All telemetry is attributed to a specific identity automatically.
Enterprise Certificate-based authentication with lifecycle management, rotation, and revocation. Hush issues short-lived, just-in-time credentials at runtime and attest identity via the SPIFFE framework. Lifecycle is managed automatically. No manual rotation required.
Advanced Hardware-backed identity stored in HSMs or TPMs. Remote attestation to verify agent integrity before granting access. Confidential computing enclaves for sensitive operations. Hush operates on-premises and in hybrid environments, keeping credential issuance within the customer’s own infrastructure boundary. SPIFFE-based identity provides the cryptographic foundation that hardware-bound identity and attestation builds on.

Least Agency: The Access Control Principle Built for AI Agents

One concept I think deserves wider adoption is Least Agency, a term coined by OWASP and highlighted throughout the Anthropic framework. Least privilege constrains what a system can access. Least Agency goes further: it restricts what each agent tool can do, how often, and from where. An email-drafting agent needs email permissions, not access to the finance file share.

This matters because most credential systems are not built to express task-scoped permissions at the agent level. Approved actions, prohibited actions, escalation triggers, and scope limits all need to be explicit and enforced at the access layer, not just declared in agent instructions.

Hush enforces Least Agency through runtime policy. Machine-to-machine interactions are mapped continuously and converted into access policies that define exactly which workloads can reach which services. Any connection outside that policy is blocked at the point of access. The capabilities that deliver this:

  • Runtime Visibility and Discovery: continuous discovery of every workload, service, and AI agent from code to production, including shadow credentials and NHIs not visible in static scans.
  • Just-in-Time Scoped Access: credentials issued at the moment of access, scoped to the exact task, expired immediately after use. No standing access for agents to misuse.
  • Runtime Posture Analysis: risks prioritized based on actual runtime behavior and blast radius, not static configuration.
  • No Code or Application Changes: lightweight sensors run transparently in the background.

MCP Security and Supply Chain Risk for AI Agent Deployments

The framework’s section on MCP security and supply chain risk is one I recommend reading carefully. AI agent deployments compose capabilities at runtime, loading tools and personas dynamically from external sources. Traditional software composition analysis was not designed for this model, and the attack surface it creates is underappreciated.

Tool chaining attacks illustrate why this is hard to catch. An attacker does not need to compromise a single high-privilege tool. Instead, they manipulate an agent into combining two legitimate, low-privilege tools in a sequence that exposes data neither would surface on its own. Every command runs through trusted binaries under valid credentials, so host-based monitoring has nothing to flag. The access looks correct because the credentials are legitimate.

Running MCP servers on immutable infrastructure after code verification, signing them cryptographically, and requiring identity-based authentication for every tool connection is the right prescription. Hush enforces this at the access layer: every connection from an agent to a tool or service is governed by a named policy. If a workload is not explicitly authorized to reach a given service, the connection does not happen, regardless of what instructions the agent received. That external enforcement, sitting outside the agent itself, is what makes the control reliable.

Runtime Visibility and Incident Investigation for Non-Human Identities

Two metrics matter most before any other detection investment: dwell time, meaning how long from an anomaly to human awareness, and coverage, meaning the fraction of alerts actually investigated. Both depend entirely on attribution. Without knowing which specific agent instance made a decision or accessed a resource, you cannot trace the chain of events that produced an incident. You can measure that something went wrong. You cannot explain how.

Hush provides runtime telemetry with identity attribution for every workload and agent action. Because Hush facilitates the access itself, every connection is logged against the verified identity that initiated it. The visual lineage map shows exactly which agents connect to which services, what credentials they use, and when, giving security teams the starting point they need to reconstruct an incident rather than beginning from a pile of unattributed events. For teams dealing with compliance requirements around algorithmic explainability, that audit trail is not optional.

Implementing Zero Trust for AI Agents: Four Concrete Steps

The guide recommends beginning at Foundation and advancing tiers as deployments scale. Here is how to sequence that with Hush.

Step 1: Discover Every Non-Human Identity at Runtime

You cannot govern what you cannot see, and most teams discover NHIs and agents they did not know existed once runtime discovery is in place. Hush’s free tier provides continuous discovery across cloud, on-premises, and hybrid environments, building an inventory based on real-world usage rather than configuration assumptions. The first time most teams run it, something unexpected shows up.

Step 2: Map Your Static Secrets and Credential Exposure

Static API keys and embedded credentials are easier to find than most teams expect, and they are the first thing an AI-assisted attacker looks for. Hush detects exposed, leaked, and misconfigured secrets across code, cloud, and pipelines, surfaced with blast-radius prioritization so you know what to fix first and what the consequences of each exposure would be.

Step 3: Define Explicit Access Policies for Each Agent

An agent with vague permission to ‘help with customer service’ has no enforceable boundaries. Approved actions, prohibited actions, and scope limits need to be written down and enforced at the access layer. Hush converts observed machine-to-machine interactions into access policies automatically, giving you a starting point grounded in how your agents actually behave rather than how you assume they do.

Step 4: Replace Static Credentials with JIT Scoped Access

Start with the workload carrying the largest blast radius. Hush provisions just-in-time, scoped credentials at runtime and enforces policy at the point of access, with no code changes or infrastructure redesign required. Once one workload is running under JIT access the pattern is established. Expansion to the rest of the fleet follows the same process.

The Identity Access Layer That Makes Zero Trust for AI Agents Practical

What I find most valuable about the Anthropic framework is that it does not let you off the hook with vague principles. The tier structure forces a real question: are you at Foundation, or are you below it? Most teams, when they look honestly at their agent deployments, find they are below it. Not because they made bad decisions, but because the identity and access infrastructure the framework assumes has not existed in a practical, deployable form until recently.

That is what Hush is built to change. The framework sets the destination. We give you the access layer to get there from day one, without a multi-year infrastructure overhaul standing in the way.

If you want to see how it works in practice, get started for free or schedule a demo with the team.

Find Every AI Agent and NHI, Free
Get a Demo